<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://nuculabs.dev/feed.xml" rel="self" type="application/atom+xml" /><link href="https://nuculabs.dev/" rel="alternate" type="text/html" /><updated>2026-09-30T19:34:00+03:00</updated><id>https://nuculabs.dev/feed.xml</id><title type="html">NucuLabs Blog</title><subtitle>A blog about programming, cloud and engineering.</subtitle><author><name>Denis</name></author><entry><title type="html">Meet Fluxa: a clearer picture of your money</title><link href="https://nuculabs.dev/projects/2026/09/28/meet-fluxa.html" rel="alternate" type="text/html" title="Meet Fluxa: a clearer picture of your money" /><published>2026-09-28T00:00:00+03:00</published><updated>2026-09-28T00:00:00+03:00</updated><id>https://nuculabs.dev/projects/2026/09/28/meet-fluxa</id><content type="html" xml:base="https://nuculabs.dev/projects/2026/09/28/meet-fluxa.html"><![CDATA[<p>Hello everyone! 👋</p>

<p>Have you ever opened a spreadsheet called <code class="language-plaintext highlighter-rouge">budget-final-v7-actually-final.xlsx</code>, stared at three bank apps, and still wondered where your money went? That’s the problem <a href="https://fluxa.nuculabs.dev/">Fluxa</a> is trying to make less annoying. It’s a personal finance app I’ve been building for the everyday stuff: transactions, accounts, budgets, goals, and the bigger picture beyond this month’s grocery bill.</p>

<!--more-->

<p>Here’s a tour of the parts I reach for most. <strong>All screenshots below use fictional sample data</strong>, so the numbers are examples rather than anyone’s finances.</p>

<h2 id="start-with-the-whole-picture">Start with the whole picture</h2>

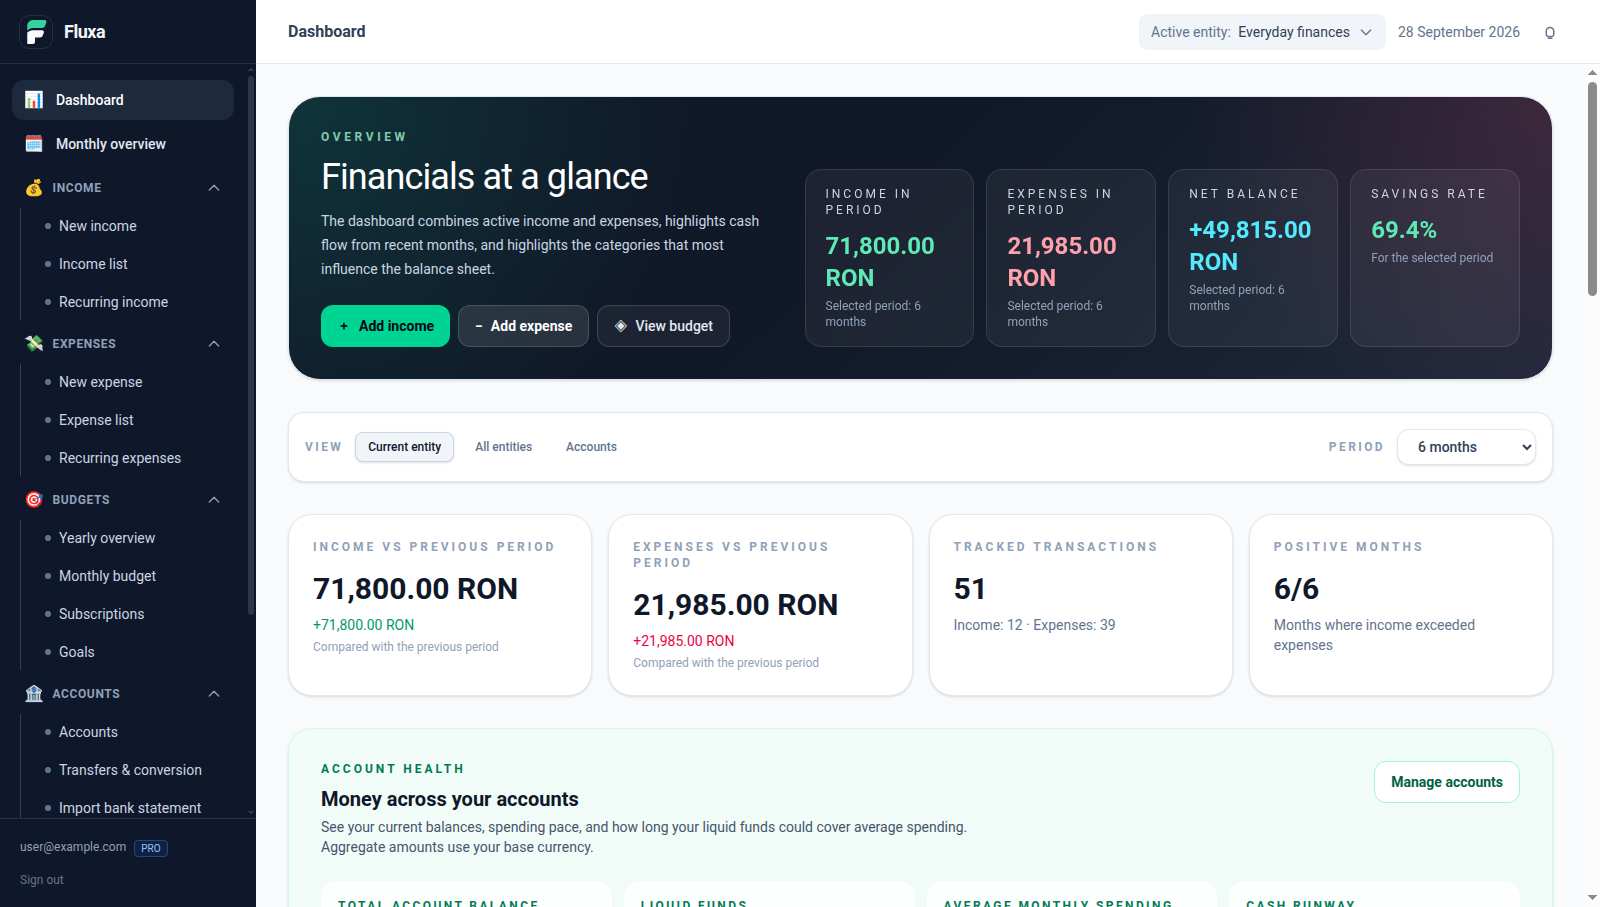
<p>Fluxa’s dashboard answers the useful questions first: how much came in, how much went out, what is left, and whether this month is behaving itself. You can switch between the current entity, all entities, and an account view, then change the time period without rebuilding a spreadsheet pivot table.</p>

<p><img src="/assets/images/2026/fluxa/dashboard.png" alt="Fluxa dashboard with six months of sample income, expenses, savings rate, and account health" /></p>

<p><em>A six-month overview for a fictional household.</em></p>

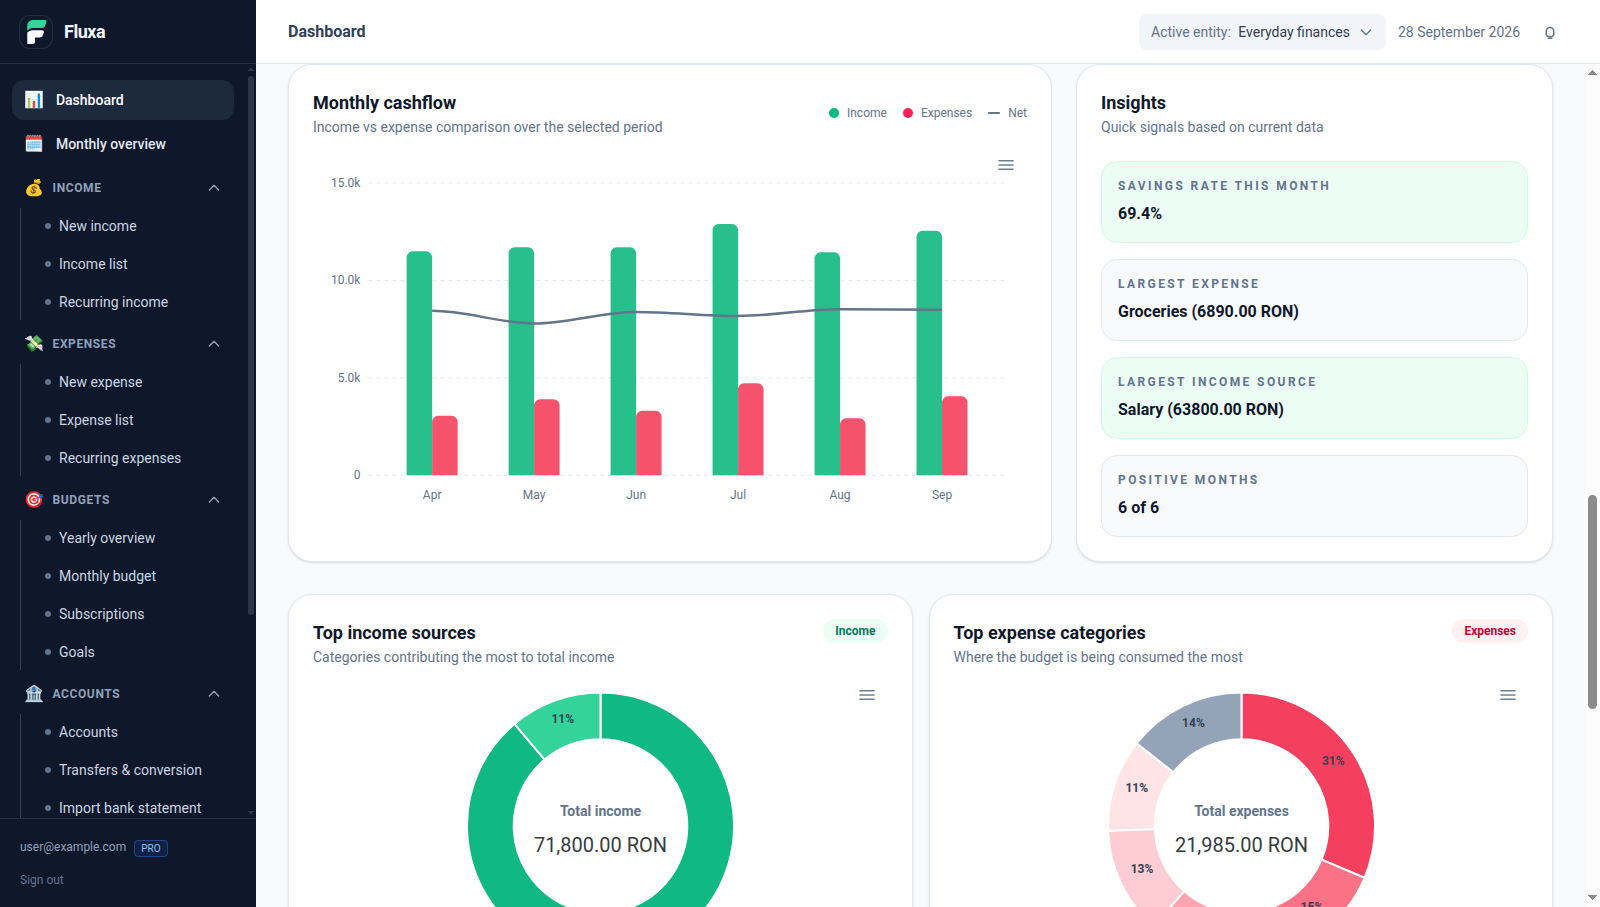
<p>The cash-flow chart puts income, expenses, and net movement together. Category breakdowns and recent activity help explain the numbers. The account health section adds balances and a cash-runway estimate, which is much more helpful than a mysterious “looks fine” feeling.</p>

<p><img src="/assets/images/2026/fluxa/cashflow.png" alt="Populated Fluxa cash-flow chart and category breakdowns for six months" /></p>

<p><em>Six months of sample activity, with enough variation to look like life rather than a copy-pasted spreadsheet.</em></p>

<h2 id="give-every-euro-or-leu-an-address">Give every euro (or leu) an address</h2>

<p>You can record income and spending against cash, bank, card, savings, and investment accounts, then move money between accounts. Fluxa also supports multiple entities, so personal finances and a PFA or side business can have their own transactions while still appearing in a combined view.</p>

<p>Transactions can be in <strong>RON, EUR, USD, GBP, or CHF</strong>. Fluxa uses ECB-based exchange rates for conversion and keeps the original currency and amount. You can choose RON, EUR, or USD as the currency for your overall totals. Recurring entries take care of predictable payments, while the subscription tracker shows what monthly and yearly services add up to and when they bill next.</p>

<h2 id="budgets-that-tell-you-something-useful">Budgets that tell you something useful</h2>

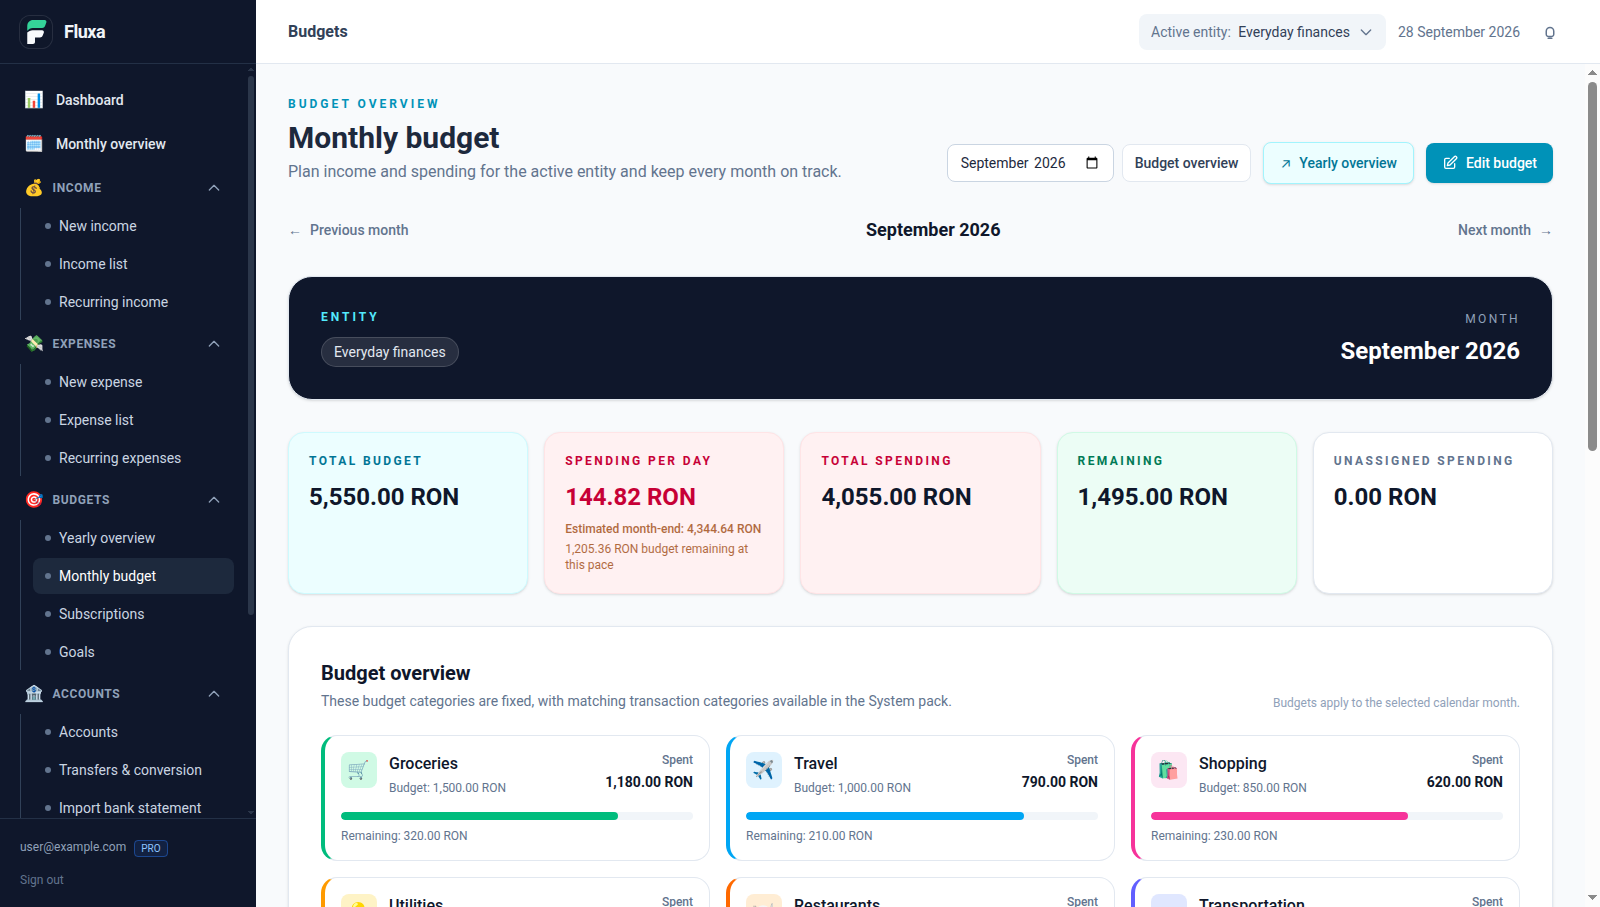
<p>A budget is more than a list of hopeful numbers. Fluxa compares each monthly category allocation with actual spending, shows what remains, and estimates where the month is heading. You can also zoom out to the yearly overview. This is where a small collection of “only 49.99” subscriptions gets its moment of truth.</p>

<p><img src="/assets/images/2026/fluxa/budget.png" alt="Fluxa monthly budget with sample allocations, actual spending, remaining amount, and category progress" /></p>

<p><em>A populated September budget: groceries, travel, shopping, and the rest all have real sample spending against them.</em></p>

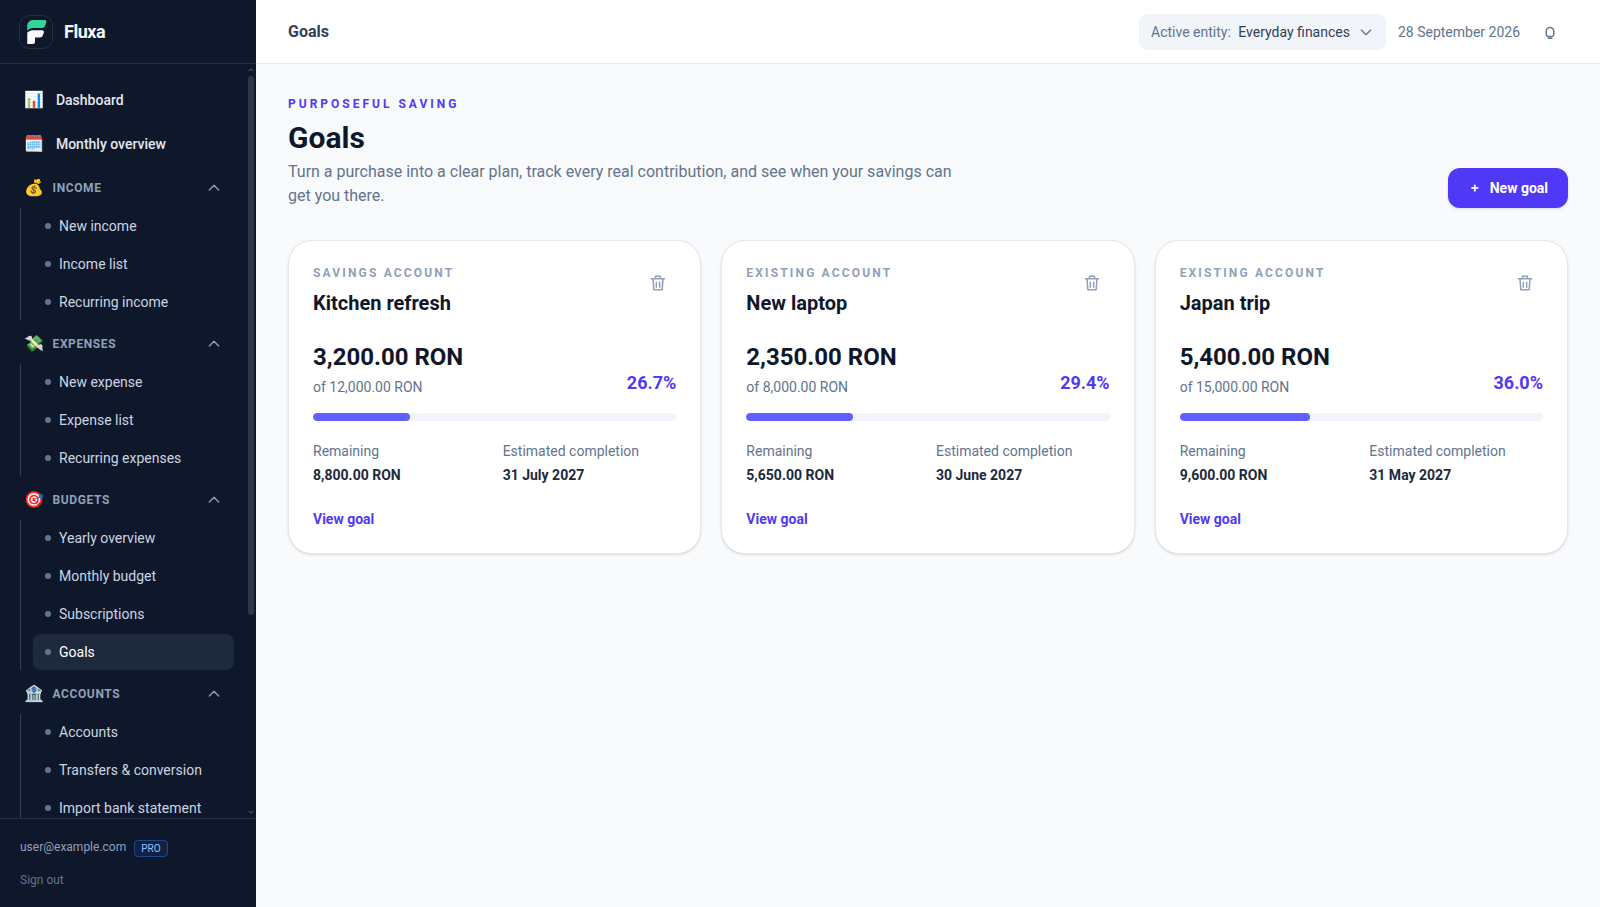
<p>Goals make the other side of planning more fun. Instead of a vague promise to save for a trip, you can give it a target, reserve money from an existing account or use a dedicated savings account, and see the progress and estimated completion date. The sample household has a Japan trip, a laptop, and a kitchen refresh underway. Apparently it has plans.</p>

<p><img src="/assets/images/2026/fluxa/goals.png" alt="Three funded Fluxa savings goals with progress bars and estimated completion dates" /></p>

<p><em>Three goals with money already set aside, not three empty progress bars.</em></p>

<h2 id="money-is-more-than-the-checking-balance">Money is more than the checking balance</h2>

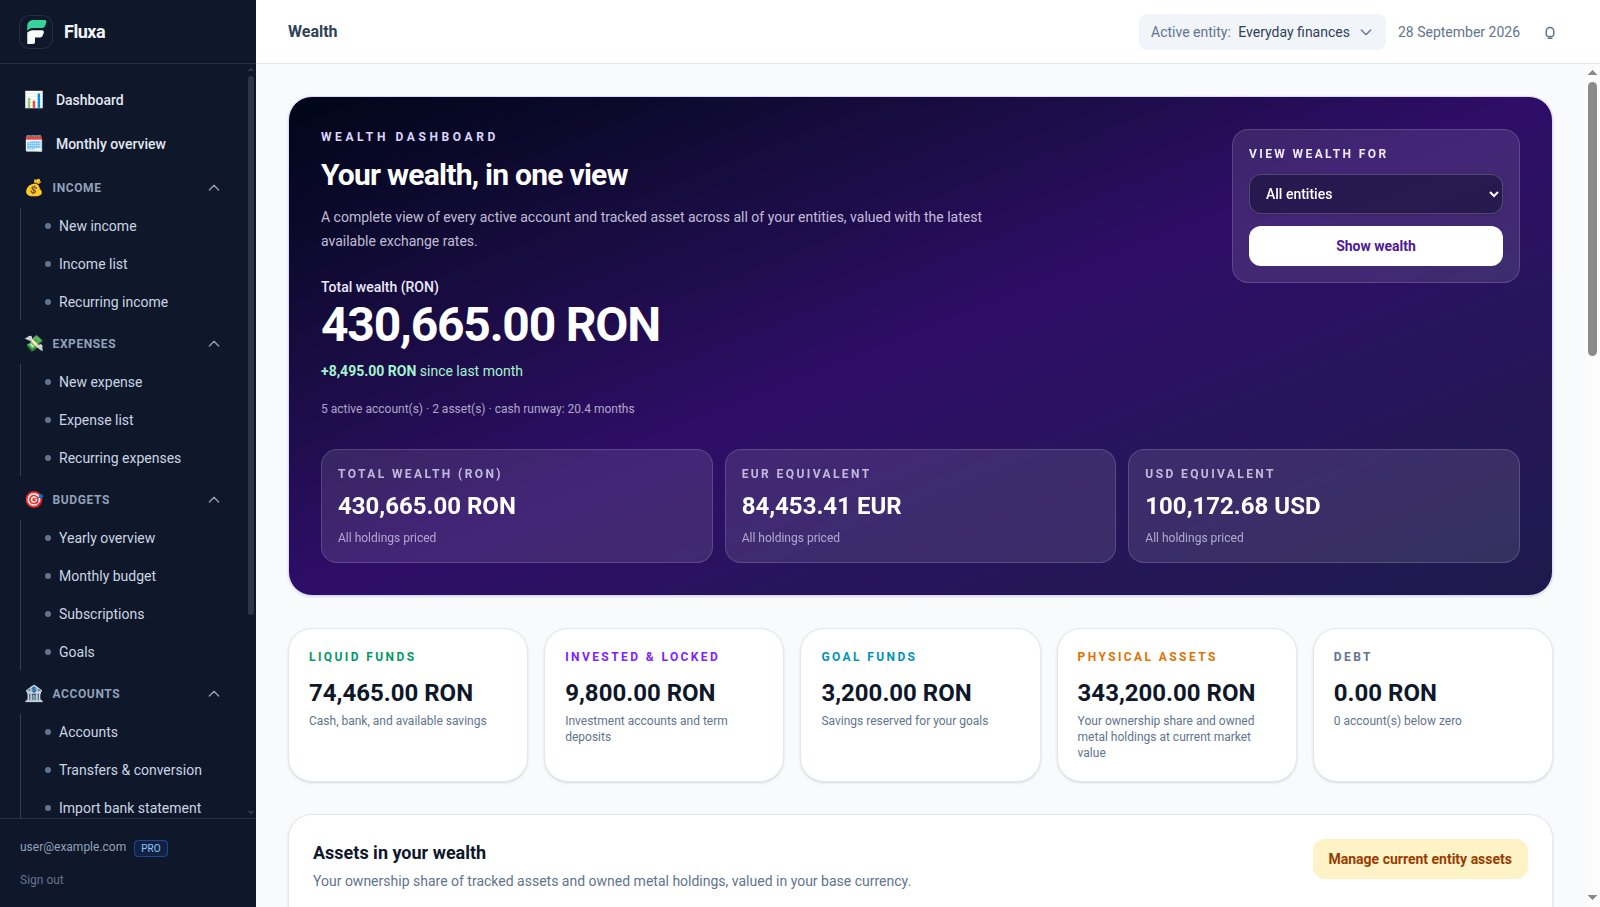
<p>Wealth brings accounts, investments, goal savings, and tracked physical assets into one view across entities. It shows native balances alongside converted totals, plus a history and an allocation chart. If you track a home, a bicycle, or physical gold and silver, those can join the picture too. The example below includes an apartment, a bicycle, an index fund, and savings.</p>

<p><img src="/assets/images/2026/fluxa/wealth.png" alt="Fluxa wealth dashboard with populated account, investment, goal, and physical-asset totals" /></p>

<p><em>A fictional portfolio with liquid funds, investments, goal money, and physical assets.</em></p>

<h2 id="less-typing-more-checking">Less typing, more checking</h2>

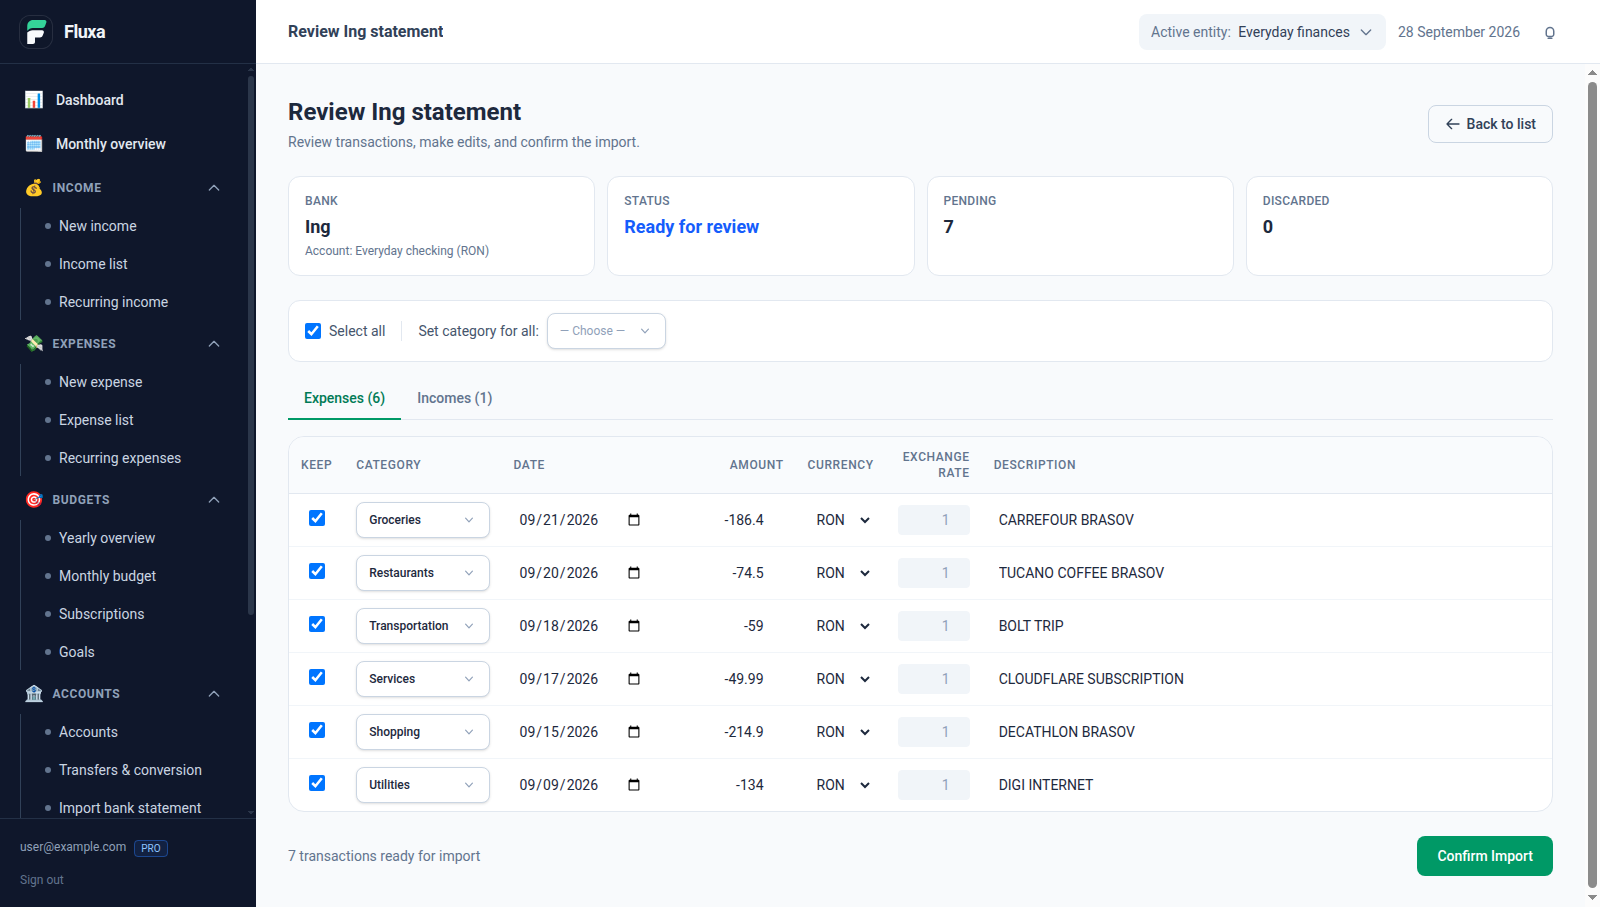
<p>The <strong>Pro bank-statement importer</strong> can parse statements from BRD, ING, Revolut, and UniCredit, including Revolut CSV exports. The important part is the review step: check dates and amounts, adjust categories or descriptions, discard rows you don’t want, and only then confirm the import. If you confirm the wrong batch, you can reverse it.</p>

<p><img src="/assets/images/2026/fluxa/import-review.png" alt="Fluxa ING statement review with seven categorized sample transactions ready for confirmation" /></p>

<p><em>Illustrative statement-review data, including groceries, transport, services, and one income entry.</em></p>

<p>There are a few other touches I appreciate: a Romanian <strong>Registru Jurnal</strong> export in PDF and Excel, light and dark themes, English, Romanian, and German, and an installable web app that can queue new income or expense entries while offline and sync them later. Fluxa can also split a shared bill and track recurring transactions, so the little chores have a place too.</p>

<p>Fluxa is for the moment when you want an answer, not another tab. If that sounds useful, <a href="https://fluxa.nuculabs.dev/">give Fluxa a try</a> and tell me which part of your money spreadsheet you would most like to retire.</p>

<hr />

<p><em>Thanks to OpenAI Codex for helping draft this article, preparing the fictional demo data, and capturing the screenshots.</em></p>]]></content><author><name>Denis</name></author><category term="Projects" /><category term="fluxa" /><category term="personal finance" /><category term="ruby on rails" /><category term="vue" /><summary type="html"><![CDATA[Hello everyone! 👋 Have you ever opened a spreadsheet called budget-final-v7-actually-final.xlsx, stared at three bank apps, and still wondered where your money went? That’s the problem Fluxa is trying to make less annoying. It’s a personal finance app I’ve been building for the everyday stuff: transactions, accounts, budgets, goals, and the bigger picture beyond this month’s grocery bill.]]></summary></entry><entry><title type="html">A tour of concurrency in Python</title><link href="https://nuculabs.dev/python/2026/09/26/a-tour-of-concurrency-in-python.html" rel="alternate" type="text/html" title="A tour of concurrency in Python" /><published>2026-09-26T00:00:00+03:00</published><updated>2026-09-26T00:00:00+03:00</updated><id>https://nuculabs.dev/python/2026/09/26/a-tour-of-concurrency-in-python</id><content type="html" xml:base="https://nuculabs.dev/python/2026/09/26/a-tour-of-concurrency-in-python.html"><![CDATA[<h1 id="introduction">Introduction</h1>

<p>Hello everyone! 👋</p>

<p>This article will be a simple and basic tour of Python’s concurrency models. We’ll start with threads, then
move to processes, and finally we will cover asyncio. I’ll show you how to interact with these
mechanisms using some low-level APIs then move to higher-level more modern APIs. I’ll also show
you some utility primitives for synchronization.</p>

<p>I won’t cover all of it because all the info is available on the official Python documentation
website but after reading this article you will have a good understanding of Python’s concurrency
model.</p>

<h1 id="threads">Threads</h1>

<p>One of the main concurrency models are threads. Your program runs inside a Process and inside the process
there are multiple threads. Because threads run inside a process container they <strong>share all the resources</strong> from
that process.</p>

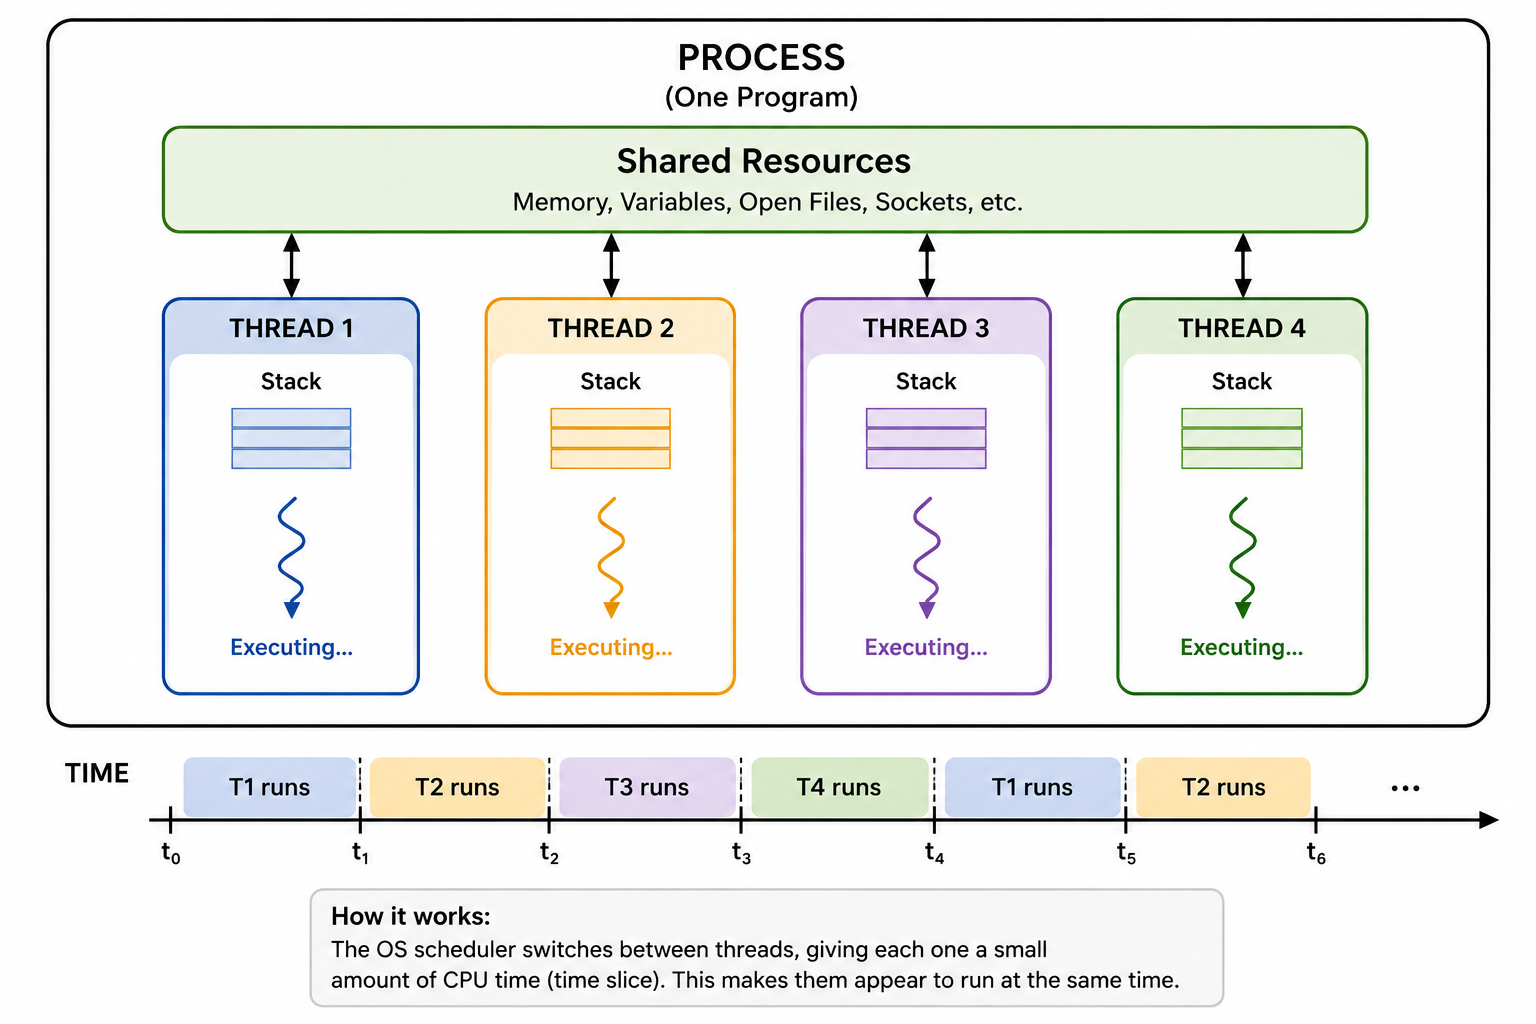
<p>Threads may appear to run in parallel at the same time but in fact they don’t. Python has the <strong>GIL</strong>
(Global Interpreter Lock) and because of that only one thread runs at the same time, but because they
switch so fast it appears as they’re running in parallel.</p>

<p><img src="/assets/images/2026/py-concurrency/threads-diagram.png" alt="" /></p>

<p>Back in the day computers had only one CPU core and the OS and application were sharing the core. The code could
only run on one core and for the OS to allow multitasking it needed to allocate each application
a time slice on the core, same happens today, but now we have access to multiple cores and we can run
things in parallel.</p>

<blockquote>
  <p>In other languages such as Java threads could be scheduled on different cores making them
run in parallel. But in Python, because of the GIL, it only allows one thread to run at the same time
per process.</p>
</blockquote>

<p>Threads are lightweight compared to Processes, but they are also expensive when compared to coroutines.</p>

<table>
  <thead>
    <tr>
      <th> </th>
      <th style="text-align: right">Coroutine</th>
      <th style="text-align: right">Thread</th>
      <th style="text-align: right">Process</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Creation</td>
      <td style="text-align: right">Very cheap</td>
      <td style="text-align: right">Moderate</td>
      <td style="text-align: right">Expensive</td>
    </tr>
    <tr>
      <td>Memory</td>
      <td style="text-align: right">Very low</td>
      <td style="text-align: right">Higher</td>
      <td style="text-align: right">Much higher</td>
    </tr>
    <tr>
      <td>Context switch</td>
      <td style="text-align: right">Very cheap</td>
      <td style="text-align: right">OS-level, more expensive</td>
      <td style="text-align: right">OS-level, most expensive</td>
    </tr>
    <tr>
      <td>Memory space</td>
      <td style="text-align: right">Shared</td>
      <td style="text-align: right">Shared</td>
      <td style="text-align: right">Separate</td>
    </tr>
    <tr>
      <td>Scheduling</td>
      <td style="text-align: right">Event loop</td>
      <td style="text-align: right">OS</td>
      <td style="text-align: right">OS</td>
    </tr>
    <tr>
      <td>Typical scale</td>
      <td style="text-align: right">Thousands–millions*</td>
      <td style="text-align: right">Hundreds–thousands</td>
      <td style="text-align: right">Usually relatively few</td>
    </tr>
  </tbody>
</table>

<p>Because when creating a thread you need create the shared resources as well, each thread has its own
stack and this does not scale well if you try to create a million threads. The OS code
which manages the threads also needs to schedule them, and if there are many threads to be scheduled
then it will hit a bottleneck and the performance will drop. Same thing goes with processes.</p>

<blockquote>
  <p>A fork bomb is a type of “virus” that forks indefinitely, the OS will create the processes
until all resources are exhausted, and they can’t be scheduled reliably forcing the system to crash.</p>
</blockquote>

<h2 id="thread">Thread</h2>

<p>This is some example code that starts two threads, the target is the <code class="language-plaintext highlighter-rouge">thread_target</code> function which will be run on the
two threads.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="kn">import</span> <span class="n">random</span></span><span class="code-line"><span class="kn">from</span> <span class="n">threading</span> <span class="kn">import</span> <span class="n">Thread</span></span><span class="code-line"></span><span class="code-line"></span><span class="code-line"><span class="k">class</span> <span class="nc">Program</span><span class="p">:</span></span><span class="code-line">    <span class="k">def</span> <span class="nf">__init__</span><span class="p">(</span><span class="n">self</span><span class="p">):</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_shared_x</span> <span class="o">=</span> <span class="mi">2</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">thread_target</span><span class="p">(</span><span class="n">self</span><span class="p">):</span></span><span class="code-line">        <span class="nf">print</span><span class="p">(</span><span class="sh">"</span><span class="s">Hello from thread</span><span class="sh">"</span><span class="p">)</span></span><span class="code-line">        <span class="k">for</span> <span class="n">i</span> <span class="ow">in</span> <span class="nf">range</span><span class="p">(</span><span class="mi">1_000_000</span><span class="p">):</span></span><span class="code-line">            <span class="n">self</span><span class="p">.</span><span class="n">_shared_x</span> <span class="o">+=</span> <span class="n">random</span><span class="p">.</span><span class="nf">randint</span><span class="p">(</span><span class="mi">0</span><span class="p">,</span> <span class="n">i</span><span class="p">)</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">main</span><span class="p">(</span><span class="n">self</span><span class="p">):</span></span><span class="code-line">        <span class="n">th_one</span> <span class="o">=</span> <span class="nc">Thread</span><span class="p">(</span><span class="n">target</span><span class="o">=</span><span class="n">self</span><span class="p">.</span><span class="n">thread_target</span><span class="p">)</span></span><span class="code-line">        <span class="n">th_two</span> <span class="o">=</span> <span class="nc">Thread</span><span class="p">(</span><span class="n">target</span><span class="o">=</span><span class="n">self</span><span class="p">.</span><span class="n">thread_target</span><span class="p">)</span></span><span class="code-line">        <span class="n">th_one</span><span class="p">.</span><span class="nf">start</span><span class="p">()</span></span><span class="code-line">        <span class="n">th_two</span><span class="p">.</span><span class="nf">start</span><span class="p">()</span></span><span class="code-line"></span><span class="code-line">        <span class="n">th_one</span><span class="p">.</span><span class="nf">join</span><span class="p">()</span></span><span class="code-line">        <span class="n">th_two</span><span class="p">.</span><span class="nf">join</span><span class="p">()</span></span><span class="code-line"></span><span class="code-line">        <span class="nf">print</span><span class="p">(</span><span class="sh">"</span><span class="s">Shared X:</span><span class="sh">"</span><span class="p">,</span> <span class="n">self</span><span class="p">.</span><span class="n">_shared_x</span><span class="p">)</span></span><span class="code-line"></span><span class="code-line"></span><span class="code-line"><span class="k">if</span> <span class="n">__name__</span> <span class="o">==</span> <span class="sh">'</span><span class="s">__main__</span><span class="sh">'</span><span class="p">:</span></span><span class="code-line">    <span class="n">program</span> <span class="o">=</span> <span class="nc">Program</span><span class="p">()</span></span><span class="code-line">    <span class="n">program</span><span class="p">.</span><span class="nf">main</span><span class="p">()</span></span></code></pre></div></div>

<p>We need to join the threads because if we don’t, the main thread will finish and the process will exit, leaving the
other two threads orphaned.</p>

<h2 id="timer">Timer</h2>

<p>The Timer is a nice utility class that you can use when you want to schedule an action. It starts its own thread and
executes that action. It’s useful to implement heart beats or checking for some things, like authorization token refreshes.</p>

<p>Here’s a simple coding example for printing a heartbeat:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="kn">from</span> <span class="n">threading</span> <span class="kn">import</span> <span class="n">Timer</span></span><span class="code-line"><span class="kn">from</span> <span class="n">time</span> <span class="kn">import</span> <span class="n">sleep</span></span><span class="code-line"></span><span class="code-line"></span><span class="code-line"><span class="k">class</span> <span class="nc">Program</span><span class="p">:</span></span><span class="code-line">    <span class="k">def</span> <span class="nf">__init__</span><span class="p">(</span><span class="n">self</span><span class="p">):</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_timer</span><span class="p">:</span> <span class="n">Timer</span> <span class="o">|</span> <span class="bp">None</span> <span class="o">=</span> <span class="nc">Timer</span><span class="p">(</span><span class="mi">5</span><span class="p">,</span> <span class="n">self</span><span class="p">.</span><span class="n">heartbeat</span><span class="p">)</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">heartbeat</span><span class="p">(</span><span class="n">self</span><span class="p">):</span></span><span class="code-line">        <span class="nf">print</span><span class="p">(</span><span class="sh">"</span><span class="s">Heartbeat</span><span class="sh">"</span><span class="p">)</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_timer</span> <span class="o">=</span> <span class="nc">Timer</span><span class="p">(</span><span class="mi">5</span><span class="p">,</span> <span class="n">self</span><span class="p">.</span><span class="n">heartbeat</span><span class="p">)</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_timer</span><span class="p">.</span><span class="nf">start</span><span class="p">()</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">run</span><span class="p">(</span><span class="n">self</span><span class="p">):</span></span><span class="code-line">        <span class="nf">print</span><span class="p">(</span><span class="sh">"</span><span class="s">Running the program.</span><span class="sh">"</span><span class="p">)</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_timer</span><span class="p">.</span><span class="nf">start</span><span class="p">()</span></span><span class="code-line">        <span class="k">while</span> <span class="bp">True</span><span class="p">:</span></span><span class="code-line">            <span class="nf">sleep</span><span class="p">(</span><span class="mi">1</span><span class="p">)</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">stop</span><span class="p">(</span><span class="n">self</span><span class="p">):</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_timer</span><span class="p">.</span><span class="nf">cancel</span><span class="p">()</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_timer</span> <span class="o">=</span> <span class="bp">None</span></span><span class="code-line"></span><span class="code-line"><span class="k">if</span> <span class="n">__name__</span> <span class="o">==</span> <span class="sh">"</span><span class="s">__main__</span><span class="sh">"</span><span class="p">:</span></span><span class="code-line">    <span class="n">program</span> <span class="o">=</span> <span class="nc">Program</span><span class="p">()</span></span><span class="code-line">    <span class="k">try</span><span class="p">:</span></span><span class="code-line">        <span class="n">program</span><span class="p">.</span><span class="nf">run</span><span class="p">()</span></span><span class="code-line">    <span class="k">except</span> <span class="nb">KeyboardInterrupt</span><span class="p">:</span></span><span class="code-line">        <span class="n">program</span><span class="p">.</span><span class="nf">stop</span><span class="p">()</span></span></code></pre></div></div>

<h2 id="concurrent-futures-thread-pool">Concurrent Futures: Thread Pool</h2>

<p>This example is similar to the first one, but it uses a higher-level API for scheduling the threads.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="kn">import</span> <span class="n">random</span></span><span class="code-line"><span class="kn">from</span> <span class="n">concurrent.futures</span> <span class="kn">import</span> <span class="n">ThreadPoolExecutor</span></span><span class="code-line"></span><span class="code-line"></span><span class="code-line"><span class="k">class</span> <span class="nc">Program</span><span class="p">:</span></span><span class="code-line">    <span class="k">def</span> <span class="nf">__init__</span><span class="p">(</span><span class="n">self</span><span class="p">):</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_shared_x</span> <span class="o">=</span> <span class="mi">2</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">thread_target</span><span class="p">(</span><span class="n">self</span><span class="p">,</span> <span class="n">low</span><span class="p">):</span></span><span class="code-line">        <span class="nf">print</span><span class="p">(</span><span class="sh">"</span><span class="s">Hello from thread</span><span class="sh">"</span><span class="p">)</span></span><span class="code-line">        <span class="k">for</span> <span class="n">i</span> <span class="ow">in</span> <span class="nf">range</span><span class="p">(</span><span class="mi">1_000_000</span><span class="p">):</span></span><span class="code-line">            <span class="n">self</span><span class="p">.</span><span class="n">_shared_x</span> <span class="o">+=</span> <span class="n">random</span><span class="p">.</span><span class="nf">randint</span><span class="p">(</span><span class="nf">min</span><span class="p">(</span><span class="n">low</span><span class="p">,</span> <span class="n">i</span><span class="p">),</span> <span class="n">i</span><span class="p">)</span></span><span class="code-line"></span><span class="code-line">        <span class="k">return</span> <span class="n">self</span><span class="p">.</span><span class="n">_shared_x</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">main</span><span class="p">(</span><span class="n">self</span><span class="p">):</span></span><span class="code-line">        <span class="n">th_pool</span> <span class="o">=</span> <span class="nc">ThreadPoolExecutor</span><span class="p">(</span><span class="n">max_workers</span><span class="o">=</span><span class="mi">5</span><span class="p">)</span></span><span class="code-line">        <span class="n">th_one</span> <span class="o">=</span> <span class="n">th_pool</span><span class="p">.</span><span class="nf">submit</span><span class="p">(</span><span class="n">self</span><span class="p">.</span><span class="n">thread_target</span><span class="p">,</span> <span class="mi">0</span><span class="p">)</span></span><span class="code-line">        <span class="n">th_two</span> <span class="o">=</span> <span class="n">th_pool</span><span class="p">.</span><span class="nf">submit</span><span class="p">(</span><span class="n">self</span><span class="p">.</span><span class="n">thread_target</span><span class="p">,</span><span class="mi">2</span><span class="p">)</span></span><span class="code-line"></span><span class="code-line">        <span class="nf">print</span><span class="p">(</span><span class="sh">"</span><span class="s">Shared X after first thread</span><span class="sh">"</span><span class="p">,</span> <span class="n">th_one</span><span class="p">.</span><span class="nf">result</span><span class="p">())</span></span><span class="code-line">        <span class="nf">print</span><span class="p">(</span><span class="sh">"</span><span class="s">Shared X after second thread</span><span class="sh">"</span><span class="p">,</span> <span class="n">th_two</span><span class="p">.</span><span class="nf">result</span><span class="p">())</span></span><span class="code-line"></span><span class="code-line">        <span class="nf">print</span><span class="p">(</span><span class="sh">"</span><span class="s">Shared X:</span><span class="sh">"</span><span class="p">,</span> <span class="n">self</span><span class="p">.</span><span class="n">_shared_x</span><span class="p">)</span></span><span class="code-line"></span><span class="code-line"></span><span class="code-line"><span class="k">if</span> <span class="n">__name__</span> <span class="o">==</span> <span class="sh">'</span><span class="s">__main__</span><span class="sh">'</span><span class="p">:</span></span><span class="code-line">    <span class="n">program</span> <span class="o">=</span> <span class="nc">Program</span><span class="p">()</span></span><span class="code-line">    <span class="n">program</span><span class="p">.</span><span class="nf">main</span><span class="p">()</span></span></code></pre></div></div>

<p>It also initializes a thread pool of fixed size. What <code class="language-plaintext highlighter-rouge">pool.submit</code> returns is a Future. You can check the result
of the future using <code class="language-plaintext highlighter-rouge">.result()</code> or the exception with <code class="language-plaintext highlighter-rouge">.exception()</code>.</p>

<p>The docs contain all the detailed functions you can call on a <a href="https://docs.python.org/3/library/asyncio-future.html#future-object">Future</a>
object.</p>

<h1 id="processes">Processes</h1>

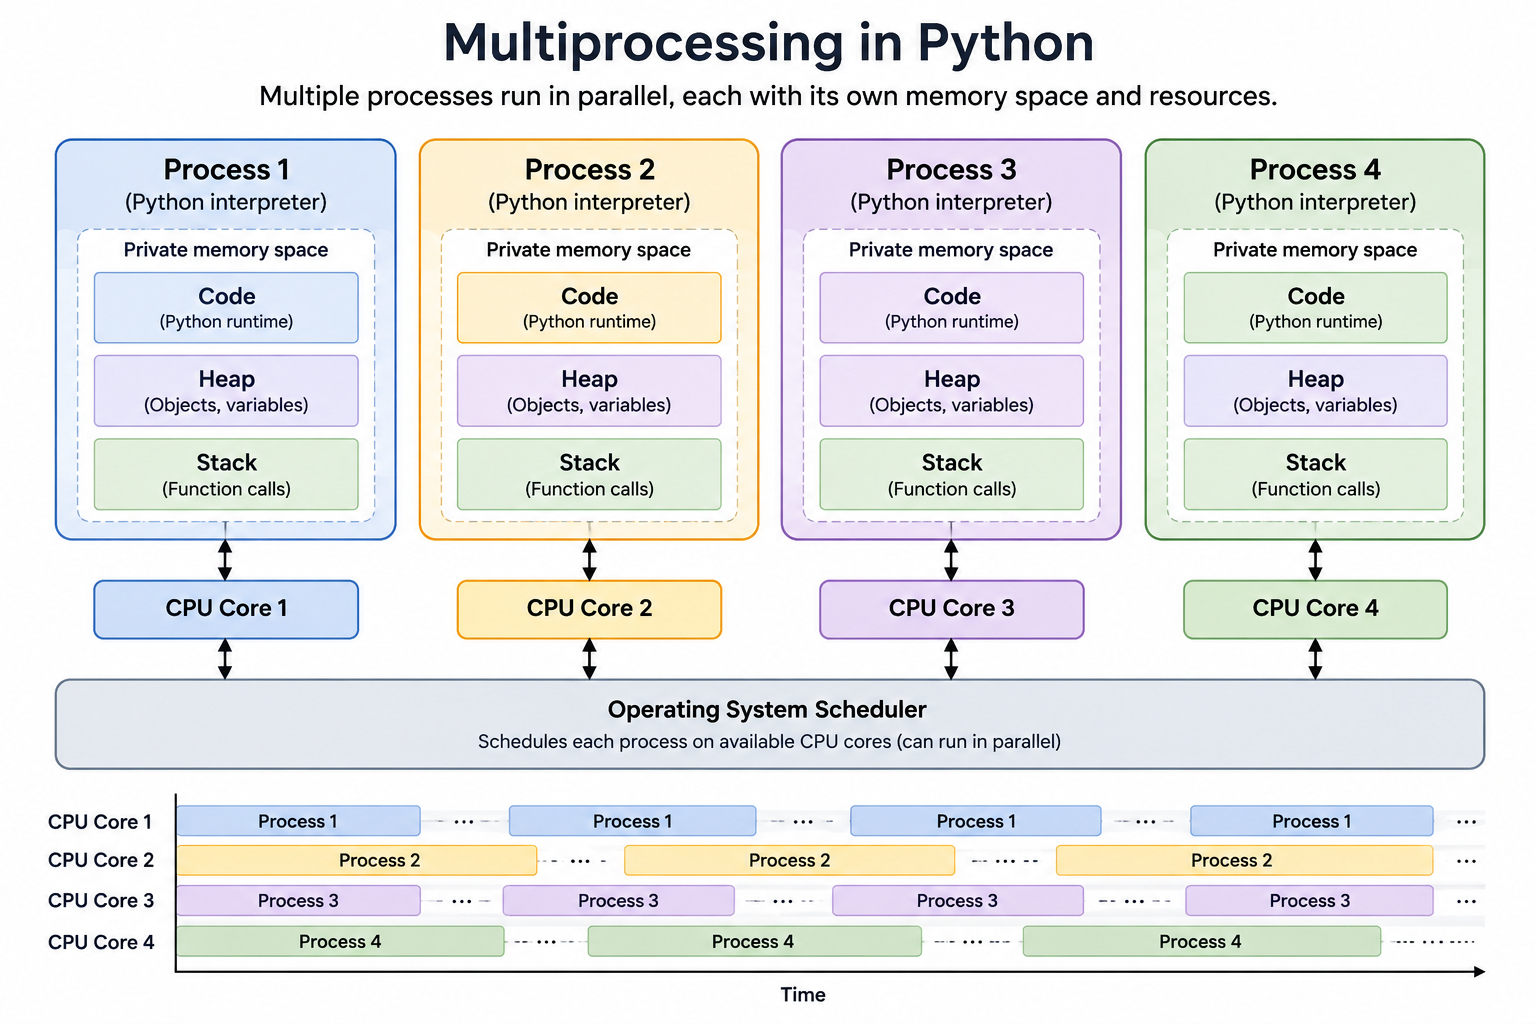
<p>Processes are managed by the operating system, and they serve as a container for threads. They are used to run things
in parallel. You can bypass Python’s GIL limitations by splitting work across processes, and if your work involves
a lot of IO or network activity you can start an async loop inside each process.</p>

<p>Creating multiple processes is a great way to tackle a CPU bound task, and because they are managed by the OS each
process runs on its own core, and if you have more processes than available cores then each process will get a time
slice on the CPU core.</p>

<p>Processes have their own private memory, but the API allows you to share some part of the memory with other processes.
To communicate between processes you can use Queues and Pipes.</p>

<p><img src="/assets/images/2026/py-concurrency/processes-diagram.png" alt="" /></p>

<h2 id="multiprocessing">Multiprocessing</h2>

<p>The multiprocessing API is similar to the threading API. You can spawn individual processes or use a process pool.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="kn">from</span> <span class="n">multiprocessing</span> <span class="kn">import</span> <span class="n">Process</span></span><span class="code-line"></span><span class="code-line"><span class="k">def</span> <span class="nf">f</span><span class="p">(</span><span class="n">name</span><span class="p">):</span></span><span class="code-line">    <span class="nf">print</span><span class="p">(</span><span class="sh">'</span><span class="s">hello</span><span class="sh">'</span><span class="p">,</span> <span class="n">name</span><span class="p">)</span></span><span class="code-line"></span><span class="code-line"><span class="k">if</span> <span class="n">__name__</span> <span class="o">==</span> <span class="sh">'</span><span class="s">__main__</span><span class="sh">'</span><span class="p">:</span></span><span class="code-line">    <span class="n">p</span> <span class="o">=</span> <span class="nc">Process</span><span class="p">(</span><span class="n">target</span><span class="o">=</span><span class="n">f</span><span class="p">,</span> <span class="n">args</span><span class="o">=</span><span class="p">(</span><span class="sh">'</span><span class="s">bob</span><span class="sh">'</span><span class="p">,))</span></span><span class="code-line">    <span class="n">p</span><span class="p">.</span><span class="nf">start</span><span class="p">()</span></span><span class="code-line">    <span class="n">p</span><span class="p">.</span><span class="nf">join</span><span class="p">()</span></span></code></pre></div></div>

<p>And a process pool example:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="kn">from</span> <span class="n">multiprocessing</span> <span class="kn">import</span> <span class="n">Pool</span></span><span class="code-line"></span><span class="code-line"><span class="k">def</span> <span class="nf">f</span><span class="p">(</span><span class="n">x</span><span class="p">):</span></span><span class="code-line">    <span class="k">return</span> <span class="n">x</span><span class="o">*</span><span class="n">x</span></span><span class="code-line"></span><span class="code-line"><span class="k">if</span> <span class="n">__name__</span> <span class="o">==</span> <span class="sh">'</span><span class="s">__main__</span><span class="sh">'</span><span class="p">:</span></span><span class="code-line">    <span class="k">with</span> <span class="nc">Pool</span><span class="p">(</span><span class="mi">5</span><span class="p">)</span> <span class="k">as</span> <span class="n">p</span><span class="p">:</span></span><span class="code-line">        <span class="nf">print</span><span class="p">(</span><span class="n">p</span><span class="p">.</span><span class="nf">map</span><span class="p">(</span><span class="n">f</span><span class="p">,</span> <span class="p">[</span><span class="mi">1</span><span class="p">,</span> <span class="mi">2</span><span class="p">,</span> <span class="mi">3</span><span class="p">]))</span></span></code></pre></div></div>

<p>The examples are copied from Python’s official <a href="https://docs.python.org/3/library/multiprocessing.html">multiprocessing</a> 
docs which is a great deep dive on the subject.</p>

<h2 id="concurrent-futures-process-pool">Concurrent Futures: Process Pool</h2>

<p>You can use the same concurrent.futures API to create a process pool like you would create a thread pool. In this
example it’s worth noticing that the _shared_x variable is not actually shared, each process gets its own copy and
the main process doesn’t modify it at all.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="kn">import</span> <span class="n">random</span></span><span class="code-line"><span class="kn">from</span> <span class="n">concurrent.futures</span> <span class="kn">import</span> <span class="n">ProcessPoolExecutor</span></span><span class="code-line"></span><span class="code-line"></span><span class="code-line"><span class="k">class</span> <span class="nc">Program</span><span class="p">:</span></span><span class="code-line">    <span class="k">def</span> <span class="nf">__init__</span><span class="p">(</span><span class="n">self</span><span class="p">):</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_shared_x</span> <span class="o">=</span> <span class="mi">2</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">target</span><span class="p">(</span><span class="n">self</span><span class="p">,</span> <span class="n">low</span><span class="p">):</span></span><span class="code-line">        <span class="nf">print</span><span class="p">(</span><span class="sh">"</span><span class="s">Hello from process</span><span class="sh">"</span><span class="p">)</span></span><span class="code-line">        <span class="k">for</span> <span class="n">i</span> <span class="ow">in</span> <span class="nf">range</span><span class="p">(</span><span class="mi">1_000_000</span><span class="p">):</span></span><span class="code-line">            <span class="n">self</span><span class="p">.</span><span class="n">_shared_x</span> <span class="o">+=</span> <span class="n">random</span><span class="p">.</span><span class="nf">randint</span><span class="p">(</span><span class="nf">min</span><span class="p">(</span><span class="n">low</span><span class="p">,</span> <span class="n">i</span><span class="p">),</span> <span class="n">i</span><span class="p">)</span></span><span class="code-line"></span><span class="code-line">        <span class="k">return</span> <span class="n">self</span><span class="p">.</span><span class="n">_shared_x</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">main</span><span class="p">(</span><span class="n">self</span><span class="p">):</span></span><span class="code-line">        <span class="n">process_pool</span> <span class="o">=</span> <span class="nc">ProcessPoolExecutor</span><span class="p">(</span><span class="n">max_workers</span><span class="o">=</span><span class="mi">5</span><span class="p">)</span></span><span class="code-line">        <span class="n">th_one</span> <span class="o">=</span> <span class="n">process_pool</span><span class="p">.</span><span class="nf">submit</span><span class="p">(</span><span class="n">self</span><span class="p">.</span><span class="n">target</span><span class="p">,</span> <span class="mi">0</span><span class="p">)</span></span><span class="code-line">        <span class="n">th_two</span> <span class="o">=</span> <span class="n">process_pool</span><span class="p">.</span><span class="nf">submit</span><span class="p">(</span><span class="n">self</span><span class="p">.</span><span class="n">target</span><span class="p">,</span><span class="mi">2</span><span class="p">)</span></span><span class="code-line"></span><span class="code-line">        <span class="nf">print</span><span class="p">(</span><span class="sh">"</span><span class="s">Shared X after first process</span><span class="sh">"</span><span class="p">,</span> <span class="n">th_one</span><span class="p">.</span><span class="nf">result</span><span class="p">())</span></span><span class="code-line">        <span class="nf">print</span><span class="p">(</span><span class="sh">"</span><span class="s">Shared X after second process</span><span class="sh">"</span><span class="p">,</span> <span class="n">th_two</span><span class="p">.</span><span class="nf">result</span><span class="p">())</span></span><span class="code-line"></span><span class="code-line">        <span class="nf">print</span><span class="p">(</span><span class="sh">"</span><span class="s">Shared X:</span><span class="sh">"</span><span class="p">,</span> <span class="n">self</span><span class="p">.</span><span class="n">_shared_x</span><span class="p">)</span></span><span class="code-line"></span><span class="code-line"></span><span class="code-line"><span class="k">if</span> <span class="n">__name__</span> <span class="o">==</span> <span class="sh">'</span><span class="s">__main__</span><span class="sh">'</span><span class="p">:</span></span><span class="code-line">    <span class="n">program</span> <span class="o">=</span> <span class="nc">Program</span><span class="p">()</span></span><span class="code-line">    <span class="n">program</span><span class="p">.</span><span class="nf">main</span><span class="p">()</span></span></code></pre></div></div>

<p>If you run the example it should print something like:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line">Hello from process</span><span class="code-line">Hello from process</span><span class="code-line">Shared X after first process 250199267754</span><span class="code-line">Shared X after second process 249818236816</span><span class="code-line">Shared X: 2</span></code></pre></div></div>

<h1 id="asyncio">Asyncio</h1>

<p>Asyncio is one of my favorite concurrency models in Python. When developing web services you usually want to serve
multiple users at the same time. Before this model was used, this was achieved by creating a thread or a process
for each request. This worked fine, but it does not scale well, there’s a limit of how many processes we can create
and schedule and same thing goes with the threads.</p>

<p>And let’s be honest with today’s Web APIs most requests are just fetching some data from some database, cache, 
make a network call or crunching some numbers. Creating a new process for every request would be overkill.</p>

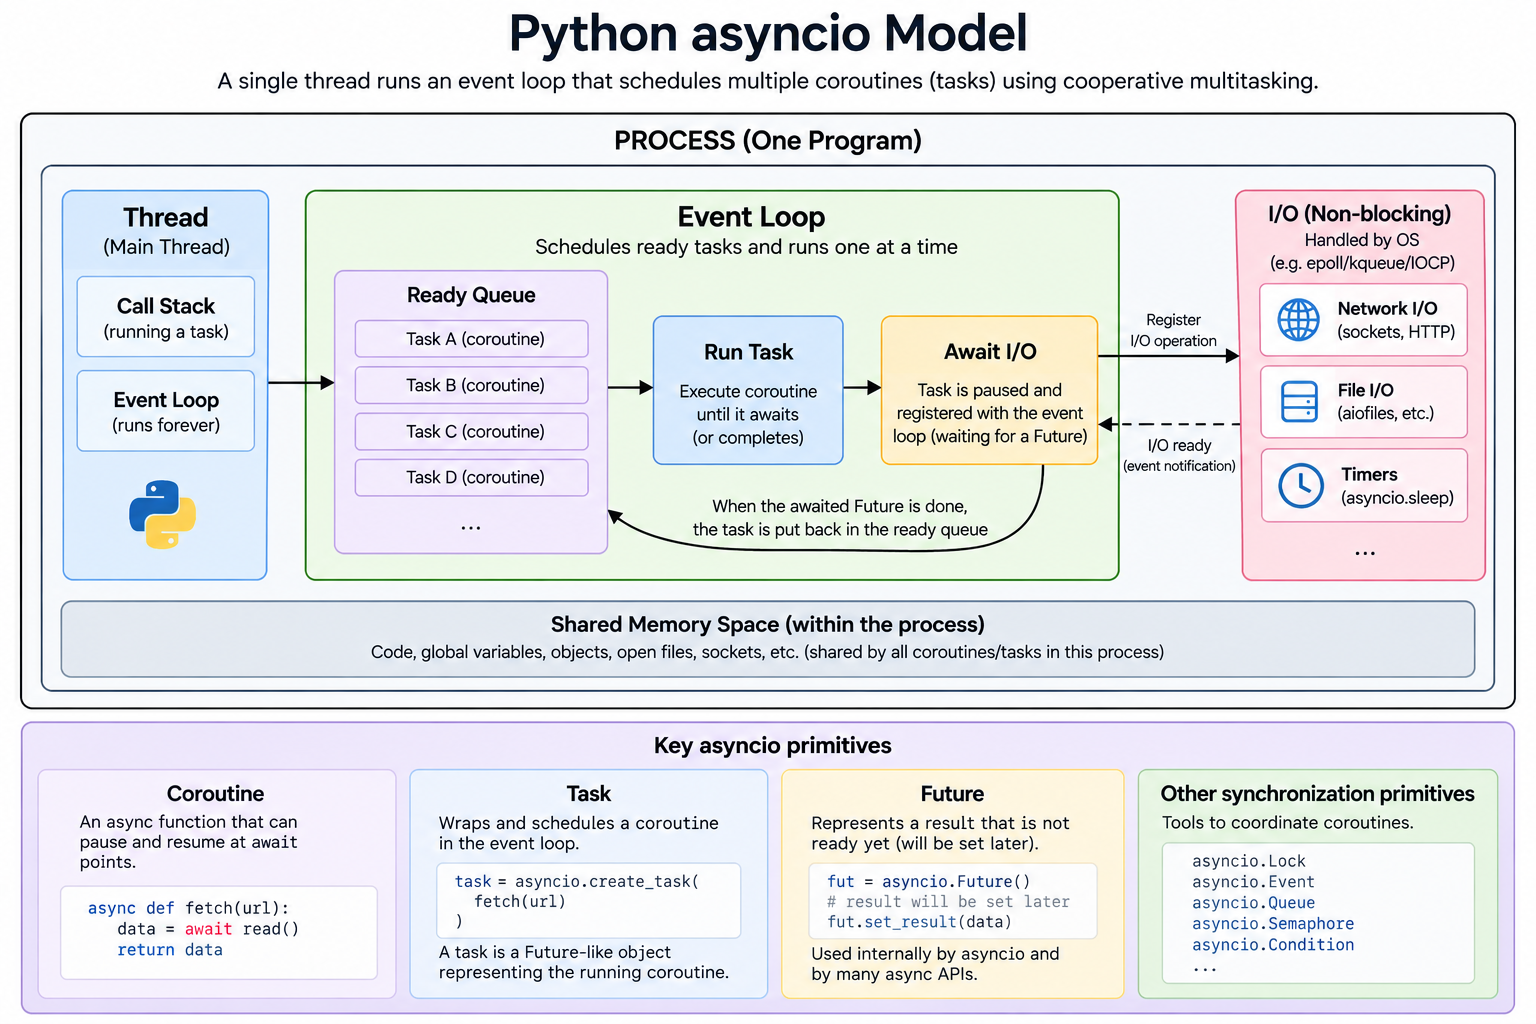
<p>An application built with asyncio in mind usually uses a single process, and on that process the event loop runs, instead
of threads we use coroutines, which are similar.</p>

<p>Threads are usually managed by the operating system and this is less efficient and coroutines are managed by the Python
interpreter. Threads get interrupted by the OS in order to let other threads/processes run and coroutines tell you
exactly when they can be interrupted by using a keyword like <code class="language-plaintext highlighter-rouge">await</code>.</p>

<p><img src="/assets/images/2026/py-concurrency/asyncio-diagram.png" alt="" /></p>

<p>When a coroutine voluntarily yields execution back to the event loop, the event loop picks another coroutine to run.
It’s very important than when using this model the coroutine doesn’t block the event loop by never <code class="language-plaintext highlighter-rouge">awaiting</code> other
tasks or spends a lot of time crunching numbers because the event loop is single threaded and that means that other
things will not run anymore.</p>

<p>This model works great for web applications because they serve requests in parallel, but if you’re writing a simple script
that makes requests in a synchronous way then you won’t benefit much, for example:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="kn">import</span> <span class="n">asyncio</span></span><span class="code-line"></span><span class="code-line"><span class="k">async</span> <span class="k">def</span> <span class="nf">task</span><span class="p">():</span></span><span class="code-line">    <span class="k">await</span> <span class="nf">fetch_data</span><span class="p">()</span>  <span class="c1"># wait until finished</span></span><span class="code-line">    <span class="k">await</span> <span class="nf">fetch_data</span><span class="p">()</span>  <span class="c1"># then start this</span></span><span class="code-line">    <span class="k">await</span> <span class="nf">fetch_data</span><span class="p">()</span></span><span class="code-line">    <span class="k">await</span> <span class="nf">fetch_data</span><span class="p">()</span></span><span class="code-line">    </span><span class="code-line"><span class="n">asyncio</span><span class="p">.</span><span class="nf">run</span><span class="p">(</span><span class="nf">task</span><span class="p">())</span></span></code></pre></div></div>

<p>If you can, run all the requests in parallel with <code class="language-plaintext highlighter-rouge">asyncio.gather</code> or more modern alternative <code class="language-plaintext highlighter-rouge">TaskGroup</code>.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="k">async</span> <span class="k">def</span> <span class="nf">fetch_data</span><span class="p">(</span><span class="n">n</span><span class="p">):</span></span><span class="code-line">    <span class="nf">print</span><span class="p">(</span><span class="sa">f</span><span class="sh">"</span><span class="s">Fetching </span><span class="si">{</span><span class="n">n</span><span class="si">}</span><span class="sh">"</span><span class="p">)</span></span><span class="code-line">    <span class="k">await</span> <span class="n">asyncio</span><span class="p">.</span><span class="nf">sleep</span><span class="p">(</span><span class="mi">1</span><span class="p">)</span></span><span class="code-line">    <span class="nf">print</span><span class="p">(</span><span class="sa">f</span><span class="sh">"</span><span class="s">Finished </span><span class="si">{</span><span class="n">n</span><span class="si">}</span><span class="sh">"</span><span class="p">)</span></span><span class="code-line">    <span class="k">return</span> <span class="n">n</span></span><span class="code-line"></span><span class="code-line"><span class="k">async</span> <span class="k">def</span> <span class="nf">main</span><span class="p">():</span></span><span class="code-line">    <span class="n">results</span> <span class="o">=</span> <span class="k">await</span> <span class="n">asyncio</span><span class="p">.</span><span class="nf">gather</span><span class="p">(</span></span><span class="code-line">        <span class="nf">fetch_data</span><span class="p">(</span><span class="mi">1</span><span class="p">),</span></span><span class="code-line">        <span class="nf">fetch_data</span><span class="p">(</span><span class="mi">2</span><span class="p">),</span></span><span class="code-line">        <span class="nf">fetch_data</span><span class="p">(</span><span class="mi">3</span><span class="p">),</span></span><span class="code-line">        <span class="nf">fetch_data</span><span class="p">(</span><span class="mi">4</span><span class="p">),</span></span><span class="code-line">    <span class="p">)</span></span><span class="code-line">    <span class="nf">print</span><span class="p">(</span><span class="n">results</span><span class="p">)</span></span><span class="code-line"></span><span class="code-line"><span class="n">asyncio</span><span class="p">.</span><span class="nf">run</span><span class="p">(</span><span class="nf">main</span><span class="p">())</span></span></code></pre></div></div>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="kn">import</span> <span class="n">asyncio</span></span><span class="code-line"></span><span class="code-line"></span><span class="code-line"><span class="k">async</span> <span class="k">def</span> <span class="nf">fetch_data</span><span class="p">(</span><span class="n">n</span><span class="p">):</span></span><span class="code-line">    <span class="nf">print</span><span class="p">(</span><span class="sa">f</span><span class="sh">"</span><span class="s">Fetching </span><span class="si">{</span><span class="n">n</span><span class="si">}</span><span class="sh">"</span><span class="p">)</span></span><span class="code-line">    <span class="k">await</span> <span class="n">asyncio</span><span class="p">.</span><span class="nf">sleep</span><span class="p">(</span><span class="mi">1</span><span class="p">)</span></span><span class="code-line">    <span class="nf">print</span><span class="p">(</span><span class="sa">f</span><span class="sh">"</span><span class="s">Finished </span><span class="si">{</span><span class="n">n</span><span class="si">}</span><span class="sh">"</span><span class="p">)</span></span><span class="code-line">    <span class="k">return</span> <span class="n">n</span></span><span class="code-line"></span><span class="code-line"><span class="k">async</span> <span class="k">def</span> <span class="nf">main</span><span class="p">():</span></span><span class="code-line">    <span class="k">async</span> <span class="k">with</span> <span class="n">asyncio</span><span class="p">.</span><span class="nc">TaskGroup</span><span class="p">()</span> <span class="k">as</span> <span class="n">tg</span><span class="p">:</span></span><span class="code-line">        <span class="n">task1</span> <span class="o">=</span> <span class="n">tg</span><span class="p">.</span><span class="nf">create_task</span><span class="p">(</span><span class="nf">fetch_data</span><span class="p">(</span><span class="mi">1</span><span class="p">))</span></span><span class="code-line">        <span class="n">task2</span> <span class="o">=</span> <span class="n">tg</span><span class="p">.</span><span class="nf">create_task</span><span class="p">(</span><span class="nf">fetch_data</span><span class="p">(</span><span class="mi">2</span><span class="p">))</span></span><span class="code-line">        <span class="n">task3</span> <span class="o">=</span> <span class="n">tg</span><span class="p">.</span><span class="nf">create_task</span><span class="p">(</span><span class="nf">fetch_data</span><span class="p">(</span><span class="mi">3</span><span class="p">))</span></span><span class="code-line">        <span class="n">task4</span> <span class="o">=</span> <span class="n">tg</span><span class="p">.</span><span class="nf">create_task</span><span class="p">(</span><span class="nf">fetch_data</span><span class="p">(</span><span class="mi">4</span><span class="p">))</span></span><span class="code-line"></span><span class="code-line">    <span class="nf">print</span><span class="p">(</span><span class="n">task1</span><span class="p">.</span><span class="nf">result</span><span class="p">())</span></span><span class="code-line">    <span class="nf">print</span><span class="p">(</span><span class="n">task2</span><span class="p">.</span><span class="nf">result</span><span class="p">())</span></span><span class="code-line">    <span class="nf">print</span><span class="p">(</span><span class="n">task3</span><span class="p">.</span><span class="nf">result</span><span class="p">())</span></span><span class="code-line">    <span class="nf">print</span><span class="p">(</span><span class="n">task4</span><span class="p">.</span><span class="nf">result</span><span class="p">())</span></span><span class="code-line"></span><span class="code-line"></span><span class="code-line"><span class="n">asyncio</span><span class="p">.</span><span class="nf">run</span><span class="p">(</span><span class="nf">main</span><span class="p">())</span></span></code></pre></div></div>

<h1 id="conclusion">Conclusion</h1>

<p>I hope this article gave you a basic introduction to Python’s concurrency models. I haven’t covered synchronization
primitives, usually I’ve only used the mutex, asyncio.shield and asyncio.Lock, in my opinion when writing user applications 
and web services it’s better to keep things simpler.</p>

<p>The official Python documentation is a great resource for diving deeper in these topics.</p>

<p>Thank you for reading!</p>]]></content><author><name>Denis</name></author><category term="Python" /><category term="python" /><category term="threads" /><category term="concurrency" /><category term="multiprocessing" /><category term="asyncio" /><category term="event loop" /><summary type="html"><![CDATA[Introduction Hello everyone! 👋 This article will be a simple and basic tour of Python’s concurrency models. We’ll start with threads, then move to processes, and finally we will cover asyncio. I’ll show you how to interact with these mechanisms using some low-level APIs then move to higher-level more modern APIs. I’ll also show you some utility primitives for synchronization. I won’t cover all of it because all the info is available on the official Python documentation website but after reading this article you will have a good understanding of Python’s concurrency model. Threads One of the main concurrency models are threads. Your program runs inside a Process and inside the process there are multiple threads. Because threads run inside a process container they share all the resources from that process. Threads may appear to run in parallel at the same time but in fact they don’t. Python has the GIL (Global Interpreter Lock) and because of that only one thread runs at the same time, but because they switch so fast it appears as they’re running in parallel. Back in the day computers had only one CPU core and the OS and application were sharing the core. The code could only run on one core and for the OS to allow multitasking it needed to allocate each application a time slice on the core, same happens today, but now we have access to multiple cores and we can run things in parallel. In other languages such as Java threads could be scheduled on different cores making them run in parallel. But in Python, because of the GIL, it only allows one thread to run at the same time per process. Threads are lightweight compared to Processes, but they are also expensive when compared to coroutines.   Coroutine Thread Process Creation Very cheap Moderate Expensive Memory Very low Higher Much higher Context switch Very cheap OS-level, more expensive OS-level, most expensive Memory space Shared Shared Separate Scheduling Event loop OS OS Typical scale Thousands–millions* Hundreds–thousands Usually relatively few Because when creating a thread you need create the shared resources as well, each thread has its own stack and this does not scale well if you try to create a million threads. The OS code which manages the threads also needs to schedule them, and if there are many threads to be scheduled then it will hit a bottleneck and the performance will drop. Same thing goes with processes. A fork bomb is a type of “virus” that forks indefinitely, the OS will create the processes until all resources are exhausted, and they can’t be scheduled reliably forcing the system to crash. Thread This is some example code that starts two threads, the target is the thread_target function which will be run on the two threads. import randomfrom threading import Threadclass Program: def __init__(self): self._shared_x = 2 def thread_target(self): print("Hello from thread") for i in range(1_000_000): self._shared_x += random.randint(0, i) def main(self): th_one = Thread(target=self.thread_target) th_two = Thread(target=self.thread_target) th_one.start() th_two.start() th_one.join() th_two.join() print("Shared X:", self._shared_x)if __name__ == '__main__': program = Program() program.main() We need to join the threads because if we don’t, the main thread will finish and the process will exit, leaving the other two threads orphaned. Timer The Timer is a nice utility class that you can use when you want to schedule an action. It starts its own thread and executes that action. It’s useful to implement heart beats or checking for some things, like authorization token refreshes. Here’s a simple coding example for printing a heartbeat: from threading import Timerfrom time import sleepclass Program: def __init__(self): self._timer: Timer | None = Timer(5, self.heartbeat) def heartbeat(self): print("Heartbeat") self._timer = Timer(5, self.heartbeat) self._timer.start() def run(self): print("Running the program.") self._timer.start() while True: sleep(1) def stop(self): self._timer.cancel() self._timer = Noneif __name__ == "__main__": program = Program() try: program.run() except KeyboardInterrupt: program.stop() Concurrent Futures: Thread Pool This example is similar to the first one, but it uses a higher-level API for scheduling the threads. import randomfrom concurrent.futures import ThreadPoolExecutorclass Program: def __init__(self): self._shared_x = 2 def thread_target(self, low): print("Hello from thread") for i in range(1_000_000): self._shared_x += random.randint(min(low, i), i) return self._shared_x def main(self): th_pool = ThreadPoolExecutor(max_workers=5) th_one = th_pool.submit(self.thread_target, 0) th_two = th_pool.submit(self.thread_target,2) print("Shared X after first thread", th_one.result()) print("Shared X after second thread", th_two.result()) print("Shared X:", self._shared_x)if __name__ == '__main__': program = Program() program.main() It also initializes a thread pool of fixed size. What pool.submit returns is a Future. You can check the result of the future using .result() or the exception with .exception(). The docs contain all the detailed functions you can call on a Future object. Processes Processes are managed by the operating system, and they serve as a container for threads. They are used to run things in parallel. You can bypass Python’s GIL limitations by splitting work across processes, and if your work involves a lot of IO or network activity you can start an async loop inside each process. Creating multiple processes is a great way to tackle a CPU bound task, and because they are managed by the OS each process runs on its own core, and if you have more processes than available cores then each process will get a time slice on the CPU core. Processes have their own private memory, but the API allows you to share some part of the memory with other processes. To communicate between processes you can use Queues and Pipes. Multiprocessing The multiprocessing API is similar to the threading API. You can spawn individual processes or use a process pool. from multiprocessing import Processdef f(name): print('hello', name)if __name__ == '__main__': p = Process(target=f, args=('bob',)) p.start() p.join() And a process pool example: from multiprocessing import Pooldef f(x): return x*xif __name__ == '__main__': with Pool(5) as p: print(p.map(f, [1, 2, 3])) The examples are copied from Python’s official multiprocessing docs which is a great deep dive on the subject. Concurrent Futures: Process Pool You can use the same concurrent.futures API to create a process pool like you would create a thread pool. In this example it’s worth noticing that the _shared_x variable is not actually shared, each process gets its own copy and the main process doesn’t modify it at all. import randomfrom concurrent.futures import ProcessPoolExecutorclass Program: def __init__(self): self._shared_x = 2 def target(self, low): print("Hello from process") for i in range(1_000_000): self._shared_x += random.randint(min(low, i), i) return self._shared_x def main(self): process_pool = ProcessPoolExecutor(max_workers=5) th_one = process_pool.submit(self.target, 0) th_two = process_pool.submit(self.target,2) print("Shared X after first process", th_one.result()) print("Shared X after second process", th_two.result()) print("Shared X:", self._shared_x)if __name__ == '__main__': program = Program() program.main() If you run the example it should print something like: Hello from processHello from processShared X after first process 250199267754Shared X after second process 249818236816Shared X: 2 Asyncio Asyncio is one of my favorite concurrency models in Python. When developing web services you usually want to serve multiple users at the same time. Before this model was used, this was achieved by creating a thread or a process for each request. This worked fine, but it does not scale well, there’s a limit of how many processes we can create and schedule and same thing goes with the threads. And let’s be honest with today’s Web APIs most requests are just fetching some data from some database, cache, make a network call or crunching some numbers. Creating a new process for every request would be overkill. An application built with asyncio in mind usually uses a single process, and on that process the event loop runs, instead of threads we use coroutines, which are similar. Threads are usually managed by the operating system and this is less efficient and coroutines are managed by the Python interpreter. Threads get interrupted by the OS in order to let other threads/processes run and coroutines tell you exactly when they can be interrupted by using a keyword like await. When a coroutine voluntarily yields execution back to the event loop, the event loop picks another coroutine to run. It’s very important than when using this model the coroutine doesn’t block the event loop by never awaiting other tasks or spends a lot of time crunching numbers because the event loop is single threaded and that means that other things will not run anymore. This model works great for web applications because they serve requests in parallel, but if you’re writing a simple script that makes requests in a synchronous way then you won’t benefit much, for example: import asyncioasync def task(): await fetch_data() # wait until finished await fetch_data() # then start this await fetch_data() await fetch_data() asyncio.run(task()) If you can, run all the requests in parallel with asyncio.gather or more modern alternative TaskGroup. async def fetch_data(n): print(f"Fetching {n}") await asyncio.sleep(1) print(f"Finished {n}") return nasync def main(): results = await asyncio.gather( fetch_data(1), fetch_data(2), fetch_data(3), fetch_data(4), ) print(results)asyncio.run(main()) import asyncioasync def fetch_data(n): print(f"Fetching {n}") await asyncio.sleep(1) print(f"Finished {n}") return nasync def main(): async with asyncio.TaskGroup() as tg: task1 = tg.create_task(fetch_data(1)) task2 = tg.create_task(fetch_data(2)) task3 = tg.create_task(fetch_data(3)) task4 = tg.create_task(fetch_data(4)) print(task1.result()) print(task2.result()) print(task3.result()) print(task4.result())asyncio.run(main()) Conclusion I hope this article gave you a basic introduction to Python’s concurrency models. I haven’t covered synchronization primitives, usually I’ve only used the mutex, asyncio.shield and asyncio.Lock, in my opinion when writing user applications and web services it’s better to keep things simpler. The official Python documentation is a great resource for diving deeper in these topics. Thank you for reading!]]></summary></entry><entry><title type="html">Gitlab SSH not working after 19.3 upgrade on Alma Linux</title><link href="https://nuculabs.dev/self%20hosting/2026/08/27/gitlab-ssh-not-working-after-upgrade.html" rel="alternate" type="text/html" title="Gitlab SSH not working after 19.3 upgrade on Alma Linux" /><published>2026-08-27T00:00:00+03:00</published><updated>2026-08-27T00:00:00+03:00</updated><id>https://nuculabs.dev/self%20hosting/2026/08/27/gitlab-ssh-not-working-after-upgrade</id><content type="html" xml:base="https://nuculabs.dev/self%20hosting/2026/08/27/gitlab-ssh-not-working-after-upgrade.html"><![CDATA[<p>Hello everyone!</p>
<p>I had some trouble with Gitlab these days, after I upgraded it to 19.3 together with my Alma Linux dependencies
the SSH push/pull stopped working, and the cause was a drift in the SELinux policies.</p>

<p>I tried running <code class="language-plaintext highlighter-rouge">gitlab-ctl apply-sepolicy</code>, reconfigure and other commands but nothing seemed to work. It took
me some time to find the root-cause of the issue, initially I thought that my ssh client of Fedora is borked, I also
use 1Password to manage the ssh keys. Well that was not the case, <code class="language-plaintext highlighter-rouge">ssh -vvv git@git.nuculabs.dev</code> is very verbose
and helped troubleshoot, the issue was server-side.</p>

<p>Best way to solve SELinux policies is to use <code class="language-plaintext highlighter-rouge">audit2allow</code> command, every time there’s an action that is denied by 
SELinux the daemon logs it and the above utility can help you generate rules that can be added to SELinux.</p>

<p>After several times of running the following commands I got all the missing rules.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="nb">sudo </span>ausearch <span class="nt">-m</span> AVC <span class="nt">-ts</span> recent <span class="se">\</span></span><span class="code-line">  | audit2allow</span><span class="code-line"><span class="nb">sudo </span>ausearch <span class="nt">-m</span> AVC <span class="nt">-ts</span> recent <span class="se">\</span></span><span class="code-line">  | audit2allow</span></code></pre></div></div>

<p>If you’re having the same issues you don’t have to run audit2allow, I saved the .te file which you can compile and 
package in order to install it as a SELinux module.</p>

<p>Save the following contents as “gitlab_ssh.te”</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line">module gitlab_ssh 1.0;</span><span class="code-line"></span><span class="code-line">require {</span><span class="code-line">        type sshd_session_t;</span><span class="code-line">        type gitlab_shell_t;</span><span class="code-line">        class file { getattr open read };</span><span class="code-line">        class dir { getattr search };</span><span class="code-line">}</span><span class="code-line"></span><span class="code-line">#============= sshd_session_t ==============</span><span class="code-line"></span><span class="code-line">#!!!! This avc is allowed in the current policy</span><span class="code-line">allow sshd_session_t gitlab_shell_t:dir search;</span><span class="code-line">allow sshd_session_t gitlab_shell_t:dir getattr;</span><span class="code-line"></span><span class="code-line">#!!!! This avc is allowed in the current policy</span><span class="code-line">allow sshd_session_t gitlab_shell_t:file { getattr open read };</span></code></pre></div></div>
<p>To install it execute the following commands:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line">➜  ~ checkmodule <span class="nt">-M</span> <span class="nt">-m</span> <span class="nt">-o</span> gitlab_ssh.mod gitlab_ssh.te</span><span class="code-line">➜  ~ semodule_package <span class="nt">-o</span> gitlab_ssh.pp <span class="nt">-m</span> gitlab_ssh.mod</span><span class="code-line">➜  ~ <span class="nb">sudo </span>semodule <span class="nt">-i</span> gitlab_ssh.pp</span></code></pre></div></div>

<p>That’s it! Hope I saved you some troubleshooting time.</p>]]></content><author><name>Denis</name></author><category term="Self Hosting" /><category term="cloud" /><category term="linux" /><category term="gitlab" /><summary type="html"><![CDATA[Hello everyone! I had some trouble with Gitlab these days, after I upgraded it to 19.3 together with my Alma Linux dependencies the SSH push/pull stopped working, and the cause was a drift in the SELinux policies. I tried running gitlab-ctl apply-sepolicy, reconfigure and other commands but nothing seemed to work. It took me some time to find the root-cause of the issue, initially I thought that my ssh client of Fedora is borked, I also use 1Password to manage the ssh keys. Well that was not the case, ssh -vvv git@git.nuculabs.dev is very verbose and helped troubleshoot, the issue was server-side. Best way to solve SELinux policies is to use audit2allow command, every time there’s an action that is denied by SELinux the daemon logs it and the above utility can help you generate rules that can be added to SELinux. After several times of running the following commands I got all the missing rules. sudo ausearch -m AVC -ts recent \ | audit2allowsudo ausearch -m AVC -ts recent \ | audit2allow If you’re having the same issues you don’t have to run audit2allow, I saved the .te file which you can compile and package in order to install it as a SELinux module. Save the following contents as “gitlab_ssh.te” module gitlab_ssh 1.0;require { type sshd_session_t; type gitlab_shell_t; class file { getattr open read }; class dir { getattr search };}#============= sshd_session_t ==============#!!!! This avc is allowed in the current policyallow sshd_session_t gitlab_shell_t:dir search;allow sshd_session_t gitlab_shell_t:dir getattr;#!!!! This avc is allowed in the current policyallow sshd_session_t gitlab_shell_t:file { getattr open read }; To install it execute the following commands: ➜ ~ checkmodule -M -m -o gitlab_ssh.mod gitlab_ssh.te➜ ~ semodule_package -o gitlab_ssh.pp -m gitlab_ssh.mod➜ ~ sudo semodule -i gitlab_ssh.pp That’s it! Hope I saved you some troubleshooting time.]]></summary></entry><entry><title type="html">My experience with GLM 5.2</title><link href="https://nuculabs.dev/artificial%20intelligence/2026/08/15/my-experience-with-glm.html" rel="alternate" type="text/html" title="My experience with GLM 5.2" /><published>2026-08-15T00:00:00+03:00</published><updated>2026-08-15T00:00:00+03:00</updated><id>https://nuculabs.dev/artificial%20intelligence/2026/08/15/my-experience-with-glm</id><content type="html" xml:base="https://nuculabs.dev/artificial%20intelligence/2026/08/15/my-experience-with-glm.html"><![CDATA[<p>Hello everyone,</p>

<p>I’ve subscribed to OpenCode[1] last week just to try GLM 5.2 and so far I’m quite impressed by it. I’m using Claude Opus 4.8 daily and I’ve also used DeepSeek V4 Pro and Kimi K2.6 from time to time.</p>

<p>Overall GLM did better than Kimi on design, I’ve completely changed the theme of my blog from the default look of Jekyll Minimal Mistakes to a Terraria inspired pixel art theme.</p>

<p>Kimi started the initial theme which was interesting and it was what I was aiming for then GLM made it even better. It replaced the CSS background with an actual tile, it wrote a Python script then generated the pixel art tile then set it as the background for the blog.</p>

<p>Then it added all sorts of fun things like reworked footer, added lava particles, added achievements, added an animated header with trees and clouds, and made the header aware of day and night, winter season and other things and zombies! Overall It’s a pretty cool, I tried adding cool effects with Kimi as well but it sorta missed the mark.</p>

<p>I also used it to generate two billing sdks for my billing software SmartBill[2].</p>

<p><img src="/assets/images/2026/my-glm-experience/billling-sdk.jpg" alt="" /></p>

<p>One SDK is in Ruby[3] and the other one is in Python[4].</p>

<p>To generate the clients I gave the model the swagger spec and told it to generate clients, then I guided the model so that the code follows best practices, is structured correctly and uses modern libraries for making requests, and model validation.</p>

<p>The final test was to tell the model to add agentic skills to the repository then use those skills to create a draft bill on the platform, and it worked.</p>

<p>Having the ability to say to an agent: “Create a bill for X” and then have the invoice ready is quite cool, in my oppinion.</p>

<p>I’ve also installed the Hermes[5] agent this weekend and played arout with it for a bit, didn’t do anything fancy, just a git commit by talking with it through iMessages. I can envision a world where we can add skills like these to the agents and accomplish goals by text messages or talking to the agent.</p>

<p>However, I’m not running the agent right now. I think it’s dangerous to give it permission and access to my stuff and the subscription costs are a turn off, if you want voice, you need to pay. If you want search, you need to pay. If you want image analysis, you need to pay. You also need to pay for the model. So, I’m expecting I will have to pay to even message it in the future, right now iMessage is free.</p>

<p>I enjoy simple things and I think this “agentic” setup is way to complicated and brittle. For now I’ll just create the invoices manually and enjoy the fact that I don’t have to pay 5 different subscriptions, but this was a fun expriment.</p>

<p>[1] - <a href="https://opencode.ai/go">https://opencode.ai/go</a></p>

<p>[2] - <a href="https://www.smartbill.ro">https://www.smartbill.ro</a></p>

<p>[3] - <a href="https://github.com/dnutiu/SmartBill-Ruby-SDK">https://github.com/dnutiu/SmartBill-Ruby-SDK</a></p>

<p>[4] - <a href="https://github.com/dnutiu/SmartBill-Python-SDK">https://github.com/dnutiu/SmartBill-Python-SDK</a></p>

<p>[5] - <a href="https://hermes-agent.nousresearch.com/">https://hermes-agent.nousresearch.com/</a></p>]]></content><author><name>Denis</name></author><category term="Artificial Intelligence" /><category term="codex" /><category term="agentic coding" /><category term="programming" /><category term="glm" /><summary type="html"><![CDATA[Hello everyone, I’ve subscribed to OpenCode[1] last week just to try GLM 5.2 and so far I’m quite impressed by it. I’m using Claude Opus 4.8 daily and I’ve also used DeepSeek V4 Pro and Kimi K2.6 from time to time. Overall GLM did better than Kimi on design, I’ve completely changed the theme of my blog from the default look of Jekyll Minimal Mistakes to a Terraria inspired pixel art theme. Kimi started the initial theme which was interesting and it was what I was aiming for then GLM made it even better. It replaced the CSS background with an actual tile, it wrote a Python script then generated the pixel art tile then set it as the background for the blog. Then it added all sorts of fun things like reworked footer, added lava particles, added achievements, added an animated header with trees and clouds, and made the header aware of day and night, winter season and other things and zombies! Overall It’s a pretty cool, I tried adding cool effects with Kimi as well but it sorta missed the mark. I also used it to generate two billing sdks for my billing software SmartBill[2]. One SDK is in Ruby[3] and the other one is in Python[4]. To generate the clients I gave the model the swagger spec and told it to generate clients, then I guided the model so that the code follows best practices, is structured correctly and uses modern libraries for making requests, and model validation. The final test was to tell the model to add agentic skills to the repository then use those skills to create a draft bill on the platform, and it worked. Having the ability to say to an agent: “Create a bill for X” and then have the invoice ready is quite cool, in my oppinion. I’ve also installed the Hermes[5] agent this weekend and played arout with it for a bit, didn’t do anything fancy, just a git commit by talking with it through iMessages. I can envision a world where we can add skills like these to the agents and accomplish goals by text messages or talking to the agent. However, I’m not running the agent right now. I think it’s dangerous to give it permission and access to my stuff and the subscription costs are a turn off, if you want voice, you need to pay. If you want search, you need to pay. If you want image analysis, you need to pay. You also need to pay for the model. So, I’m expecting I will have to pay to even message it in the future, right now iMessage is free. I enjoy simple things and I think this “agentic” setup is way to complicated and brittle. For now I’ll just create the invoices manually and enjoy the fact that I don’t have to pay 5 different subscriptions, but this was a fun expriment. [1] - https://opencode.ai/go [2] - https://www.smartbill.ro [3] - https://github.com/dnutiu/SmartBill-Ruby-SDK [4] - https://github.com/dnutiu/SmartBill-Python-SDK [5] - https://hermes-agent.nousresearch.com/]]></summary></entry><entry><title type="html">Automating my Fedora setup</title><link href="https://nuculabs.dev/linux/2026/08/15/opinionated-fedora.html" rel="alternate" type="text/html" title="Automating my Fedora setup" /><published>2026-08-15T00:00:00+03:00</published><updated>2026-08-15T00:00:00+03:00</updated><id>https://nuculabs.dev/linux/2026/08/15/opinionated-fedora</id><content type="html" xml:base="https://nuculabs.dev/linux/2026/08/15/opinionated-fedora.html"><![CDATA[<p>Hi everyone!</p>

<p>I got inspired lately by <a href="https://omarchy.org/">Omarchy</a> to create a script for my own use case and that is to automate 
my Fedora setup. Thea idea is similar to the <code class="language-plaintext highlighter-rouge">omakase sushi</code> which means “I’ll leave it to you”, instead of ordering
individual pieces the sushi chef knows best what and how to serve.</p>

<p>I’ve created this script with <a href="https://openai.com/codex/">codex</a> and I’ve published it on my Gitlab and Github account:</p>

<ul>
  <li><a href="https://gitlab.nuculabs.dev/dnutiu/FedoraLaunch">https://gitlab.nuculabs.dev/dnutiu/FedoraLaunch</a></li>
  <li><a href="https://github.com/dnutiu/FedoraLaunch">https://github.com/dnutiu/FedoraLaunch</a></li>
</ul>

<p>The script is tailored to my liking and it sets up the following:</p>

<p>Development Environment:</p>
<ul>
  <li>Python and uv and pyenv</li>
  <li>Ruby and rbenv</li>
  <li>NodeJS and nvm</li>
  <li>Go</li>
  <li>Rust</li>
  <li>Java and sdkman</li>
  <li>Docker</li>
  <li>Helm</li>
</ul>

<p>It also sets up the shell to zsh and installs oh-my-zsh.</p>

<p>Software applications such as:</p>
<ul>
  <li>PrusaSlicer for 3D printing</li>
  <li>CAD Software: KiCAD, FreeCAD</li>
  <li>Snap</li>
  <li>Obsidian</li>
  <li>1Password</li>
  <li>Codex</li>
  <li>Hey Mail</li>
  <li>VLC</li>
  <li>qBittorrent</li>
  <li>Steam</li>
  <li>Zed</li>
  <li>VSCode</li>
  <li>IntelliJ</li>
</ul>

<p>Other than that it tries to detect which drivers to install for the system, it installs them along with extra codecs,
and it enables hardware acceleration. It also prepares the directory structure for mounting my NAS.</p>

<p>That’s about it! Before having this script I had to spend a few hours to install and search for all this software
in order to set up my system to my liking, and now it’s jus a few minutes.</p>

<p>Thanks for reading!</p>]]></content><author><name>Denis</name></author><category term="Linux" /><category term="linux" /><category term="fedora" /><category term="setup" /><category term="automation" /><category term="bash" /><summary type="html"><![CDATA[Hi everyone! I got inspired lately by Omarchy to create a script for my own use case and that is to automate my Fedora setup. Thea idea is similar to the omakase sushi which means “I’ll leave it to you”, instead of ordering individual pieces the sushi chef knows best what and how to serve. I’ve created this script with codex and I’ve published it on my Gitlab and Github account: https://gitlab.nuculabs.dev/dnutiu/FedoraLaunch https://github.com/dnutiu/FedoraLaunch The script is tailored to my liking and it sets up the following: Development Environment: Python and uv and pyenv Ruby and rbenv NodeJS and nvm Go Rust Java and sdkman Docker Helm It also sets up the shell to zsh and installs oh-my-zsh. Software applications such as: PrusaSlicer for 3D printing CAD Software: KiCAD, FreeCAD Snap Obsidian 1Password Codex Hey Mail VLC qBittorrent Steam Zed VSCode IntelliJ Other than that it tries to detect which drivers to install for the system, it installs them along with extra codecs, and it enables hardware acceleration. It also prepares the directory structure for mounting my NAS. That’s about it! Before having this script I had to spend a few hours to install and search for all this software in order to set up my system to my liking, and now it’s jus a few minutes. Thanks for reading!]]></summary></entry><entry><title type="html">ZSA Moonlander Split Keyboard Review</title><link href="https://nuculabs.dev/life/2026/08/01/moonlander-review.html" rel="alternate" type="text/html" title="ZSA Moonlander Split Keyboard Review" /><published>2026-08-01T00:00:00+03:00</published><updated>2026-08-01T00:00:00+03:00</updated><id>https://nuculabs.dev/life/2026/08/01/moonlander-review</id><content type="html" xml:base="https://nuculabs.dev/life/2026/08/01/moonlander-review.html"><![CDATA[<p>Hello everyone! 👋</p>

<p>It’s been a while since I’ve reviewed a keyboard on this blog. 
My latest review was for the Logitech MX Keys keyboard and since then I 
swapped two keyboards, and I’ve landed on the ZSA Moonlander, 
as a recommendation from someone more experienced with keyboards.</p>

<p>The Logitech keyboard broke after 2 years and I thought I should get another 
membrane keyboard, so I got a Keychron B1 Pro which was priced decently, 
about 50$ and it was fine for a while but it lacks illuminated keys and 
adjustment legs, I had to 3D print some legs for it which I also glued to it. 
Overall a decent keyboard for the price.</p>

<p>After that I wanted to try a mechanical keyboard and I bought the Numphy Air V2 75% 
with brown switches. I didn’t like this keyboard, I had to do a firmware update
in order to be able to configure it from the software and I couldn’t get accustomed
to the layout, it was weird. The keyboard build seemed solid though.
I returned the keyboard and the seller didn’t wait it either,
I got a full refund on it as well, it was a bit weird for me as I didn’t expect 
that and in the end I ended up selling the keyboard to someone for about 100$.</p>

<p>Next, I got the Keychron K5 Max for about 100$ with red switches. 
I was hoping the red switches would be silent but they’re not exactly silent,
they aren’t very loud either. The keyboard is great, and I’ve kept it and gave
it to my wife, the only downside is that the keycaps are not transparent and
when it’s dark you cannot directly see the illuminated letter.</p>

<p>Now I got my Moonlander split keyboard with cherry mx red silent for a bout 3 weeks,
it was quite pricey and when I received at first I thought that I made a mistake
as the layout is different and I could not type a single word on it.</p>

<p>As I started using it again and again I started to like it and I was really
impressed by the software and the configuration options.</p>

<p>You can map each key to whatever you like, and you can also customize the RGB on
it so that you can color code them.  The keycaps are transparent, and you can
see the illuminated letter at night.</p>

<p>Another surprise are the switches, the cherry mx red silent are actually silent
compared to what I previously had, there is no clicky sound, and sometimes it feels
more silent that my laptop’s membrane keyboard.</p>

<p>The configurator is web based and easy to use, I’ve used it on Windows, Linux
and macOS. On Linux you will need to add some udev rules in order to flash the
firmware and the configuration on the keyboard, the software will walk you through
and give you the rules.</p>

<p>You can’t flash the software on the keyboard without hitting the flash with a pin, 
that means it’s quite hard if not impossible to flash the firmware if you don’t
have a thin needle/pin at your disposal.</p>

<p>As far as configuration goes you can do the following:</p>
<ul>
  <li>Map each key to whatever you like when tapped.</li>
  <li>Change the key behavior when double tapped.</li>
  <li>Change the key behavior when tapped and held. (I’m not sure how this works)</li>
  <li>Change the key behavior when held.</li>
  <li>Assign a RGB color to each individual key.</li>
  <li>Assign custom actions to keys like: layer switch, combos, animations, mouse actions.</li>
  <li>Create key combos like: A + S = custom key like ESC/Print Screen</li>
  <li>Assign macros to keys, eg when a key is pressed sent: Alt+F4</li>
</ul>

<p>The configuration options are amazing, this also means that nobody will be 
able to use your keyboard if you have a custom configuration as you need to 
remember the keys or leverage the muscle memory.</p>

<p>The next great feature of the keyboard are layers, I have currently 3 layers 
configured.</p>
<ul>
  <li>The first layer is for typing</li>
  <li>The second layer is for symbols, when programming and a custom numpad.</li>
  <li>The third layer is for multimedia controls and keyboard RGB animations.</li>
</ul>

<p>Layers are pretty cool, once you get used to them, it expands dramatically 
what you can do with the keyboard:</p>

<p><img src="/assets/images/2026/moonlander-review/layer0.png" alt="" /></p>

<p><img src="/assets/images/2026/moonlander-review/layer1.png" alt="" /></p>

<hr />

<p>The best feature of the keyboard is the comfort it provides for your hands
and your posture. I mainly purchased because I was feeling pain in my hands,
and I’ve started to use compression gloves and a vertical mouse, this helped
to some degree but my pain was gone after 1 week with the keyboard.</p>

<p>As I use the keyboard I get more accustomed to it and if in the first week I
was producing 11 words pe minute compared to 90 now it’s even better.</p>

<p>That’s about it, I hope you’ve enjoyed my review, and thank you for reading! 📚</p>]]></content><author><name>Denis</name></author><category term="Life" /><category term="keyboard" /><category term="moonlander" /><category term="zsa" /><category term="Review" /><summary type="html"><![CDATA[Hello everyone! 👋 It’s been a while since I’ve reviewed a keyboard on this blog. My latest review was for the Logitech MX Keys keyboard and since then I swapped two keyboards, and I’ve landed on the ZSA Moonlander, as a recommendation from someone more experienced with keyboards. The Logitech keyboard broke after 2 years and I thought I should get another membrane keyboard, so I got a Keychron B1 Pro which was priced decently, about 50$ and it was fine for a while but it lacks illuminated keys and adjustment legs, I had to 3D print some legs for it which I also glued to it. Overall a decent keyboard for the price. After that I wanted to try a mechanical keyboard and I bought the Numphy Air V2 75% with brown switches. I didn’t like this keyboard, I had to do a firmware update in order to be able to configure it from the software and I couldn’t get accustomed to the layout, it was weird. The keyboard build seemed solid though. I returned the keyboard and the seller didn’t wait it either, I got a full refund on it as well, it was a bit weird for me as I didn’t expect that and in the end I ended up selling the keyboard to someone for about 100$. Next, I got the Keychron K5 Max for about 100$ with red switches. I was hoping the red switches would be silent but they’re not exactly silent, they aren’t very loud either. The keyboard is great, and I’ve kept it and gave it to my wife, the only downside is that the keycaps are not transparent and when it’s dark you cannot directly see the illuminated letter. Now I got my Moonlander split keyboard with cherry mx red silent for a bout 3 weeks, it was quite pricey and when I received at first I thought that I made a mistake as the layout is different and I could not type a single word on it. As I started using it again and again I started to like it and I was really impressed by the software and the configuration options. You can map each key to whatever you like, and you can also customize the RGB on it so that you can color code them. The keycaps are transparent, and you can see the illuminated letter at night. Another surprise are the switches, the cherry mx red silent are actually silent compared to what I previously had, there is no clicky sound, and sometimes it feels more silent that my laptop’s membrane keyboard. The configurator is web based and easy to use, I’ve used it on Windows, Linux and macOS. On Linux you will need to add some udev rules in order to flash the firmware and the configuration on the keyboard, the software will walk you through and give you the rules. You can’t flash the software on the keyboard without hitting the flash with a pin, that means it’s quite hard if not impossible to flash the firmware if you don’t have a thin needle/pin at your disposal. As far as configuration goes you can do the following: Map each key to whatever you like when tapped. Change the key behavior when double tapped. Change the key behavior when tapped and held. (I’m not sure how this works) Change the key behavior when held. Assign a RGB color to each individual key. Assign custom actions to keys like: layer switch, combos, animations, mouse actions. Create key combos like: A + S = custom key like ESC/Print Screen Assign macros to keys, eg when a key is pressed sent: Alt+F4 The configuration options are amazing, this also means that nobody will be able to use your keyboard if you have a custom configuration as you need to remember the keys or leverage the muscle memory. The next great feature of the keyboard are layers, I have currently 3 layers configured. The first layer is for typing The second layer is for symbols, when programming and a custom numpad. The third layer is for multimedia controls and keyboard RGB animations. Layers are pretty cool, once you get used to them, it expands dramatically what you can do with the keyboard: The best feature of the keyboard is the comfort it provides for your hands and your posture. I mainly purchased because I was feeling pain in my hands, and I’ve started to use compression gloves and a vertical mouse, this helped to some degree but my pain was gone after 1 week with the keyboard. As I use the keyboard I get more accustomed to it and if in the first week I was producing 11 words pe minute compared to 90 now it’s even better. That’s about it, I hope you’ve enjoyed my review, and thank you for reading! 📚]]></summary></entry><entry><title type="html">How to connect Nintendo Pro Controller 2 to Linux</title><link href="https://nuculabs.dev/linux/2026/07/30/nintedo-pro-controller-linux.html" rel="alternate" type="text/html" title="How to connect Nintendo Pro Controller 2 to Linux" /><published>2026-07-30T00:00:00+03:00</published><updated>2026-07-30T00:00:00+03:00</updated><id>https://nuculabs.dev/linux/2026/07/30/nintedo-pro-controller-linux</id><content type="html" xml:base="https://nuculabs.dev/linux/2026/07/30/nintedo-pro-controller-linux.html"><![CDATA[<p>Hello,</p>

<p>This is a small blog post about connecting the Nintendo Switch 2 Pro Controller to a Linux machine.</p>

<p>I use the controller on my personal PC in order to play games on Steam. Steam supports the controller and in order
for it to be seen you just need to add some new udev rules and reload them.</p>

<p>To do so, create the following file with nano:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="nb">sudo </span>nano /etc/udev/rules.d/50-nintendo-switch.rules</span></code></pre></div></div>

<p>And then paste the udev rule contents into it:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line">SUBSYSTEM=="usb", ATTR{idVendor}=="057e", ATTR{idProduct}=="2066", MODE="0666"</span><span class="code-line">SUBSYSTEM=="usb", ATTR{idVendor}=="057e", ATTR{idProduct}=="2067", MODE="0666"</span><span class="code-line">SUBSYSTEM=="usb", ATTR{idVendor}=="057e", ATTR{idProduct}=="2069", MODE="0666"</span><span class="code-line">SUBSYSTEM=="usb", ATTR{idVendor}=="057e", ATTR{idProduct}=="2073", MODE="0666"</span><span class="code-line">SUBSYSTEM=="hidraw", ATTRS{idVendor}=="057e", ATTRS{idProduct}=="2066", MODE="0666"</span><span class="code-line">SUBSYSTEM=="hidraw", ATTRS{idVendor}=="057e", ATTRS{idProduct}=="2067", MODE="0666"</span><span class="code-line">SUBSYSTEM=="hidraw", ATTRS{idVendor}=="057e", ATTRS{idProduct}=="2069", MODE="0666"</span><span class="code-line">SUBSYSTEM=="hidraw", ATTRS{idVendor}=="057e", ATTRS{idProduct}=="2073", MODE="0666"</span></code></pre></div></div>

<p>Then run:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="nb">sudo </span>udevadm control <span class="nt">--reload-rules</span></span></code></pre></div></div>

<p>That’s it! You should be able to see your controller in Steam when connected <strong>via the USB cable</strong>, bluetooth doesn’t
work yet.</p>

<p>Thanks for reading!</p>]]></content><author><name>Denis</name></author><category term="Linux" /><category term="linux" /><category term="gaming" /><category term="udev" /><category term="controller" /><summary type="html"><![CDATA[Hello, This is a small blog post about connecting the Nintendo Switch 2 Pro Controller to a Linux machine. I use the controller on my personal PC in order to play games on Steam. Steam supports the controller and in order for it to be seen you just need to add some new udev rules and reload them. To do so, create the following file with nano: sudo nano /etc/udev/rules.d/50-nintendo-switch.rules And then paste the udev rule contents into it: SUBSYSTEM=="usb", ATTR{idVendor}=="057e", ATTR{idProduct}=="2066", MODE="0666"SUBSYSTEM=="usb", ATTR{idVendor}=="057e", ATTR{idProduct}=="2067", MODE="0666"SUBSYSTEM=="usb", ATTR{idVendor}=="057e", ATTR{idProduct}=="2069", MODE="0666"SUBSYSTEM=="usb", ATTR{idVendor}=="057e", ATTR{idProduct}=="2073", MODE="0666"SUBSYSTEM=="hidraw", ATTRS{idVendor}=="057e", ATTRS{idProduct}=="2066", MODE="0666"SUBSYSTEM=="hidraw", ATTRS{idVendor}=="057e", ATTRS{idProduct}=="2067", MODE="0666"SUBSYSTEM=="hidraw", ATTRS{idVendor}=="057e", ATTRS{idProduct}=="2069", MODE="0666"SUBSYSTEM=="hidraw", ATTRS{idVendor}=="057e", ATTRS{idProduct}=="2073", MODE="0666" Then run: sudo udevadm control --reload-rules That’s it! You should be able to see your controller in Steam when connected via the USB cable, bluetooth doesn’t work yet. Thanks for reading!]]></summary></entry><entry><title type="html">Introduction to Huffman Trees</title><link href="https://nuculabs.dev/programming/python/data%20structures%20&%20algorithms/featured/2026/07/15/huffman-trees.html" rel="alternate" type="text/html" title="Introduction to Huffman Trees" /><published>2026-07-15T00:00:00+03:00</published><updated>2026-07-15T00:00:00+03:00</updated><id>https://nuculabs.dev/programming/python/data%20structures%20&amp;%20algorithms/featured/2026/07/15/huffman-trees</id><content type="html" xml:base="https://nuculabs.dev/programming/python/data%20structures%20&amp;%20algorithms/featured/2026/07/15/huffman-trees.html"><![CDATA[<p>Hello everyone! 👋</p>

<p>This article is about Huffman Trees,  I did this project in university and after ten years or so I wanted to revisit
it in order to solidify my understanding and to practice manual coding.</p>

<h1 id="introduction">Introduction</h1>

<p>The Huffman coding tree is a fundamental data structure in computer science, and it is used for lossless 
data compression and entropy coding. Huffman coding trees are already used in ZIP, Mp3, Png for compression often
not alone but with other data compression algorithms.</p>

<p>Entropy represents the randomness of the data.</p>

<p>Say <code class="language-plaintext highlighter-rouge">roooar</code>, it has 6 characters length and there are 3 unique characters, the entropy is low because of the repeating
characters, which implies less uncertainty. For <code class="language-plaintext highlighter-rouge">123456</code>, there are 6 characters and 6 unique characters, the entropy 
is high because the data looks “random”, there is more uncertainty.</p>

<p>Entropy coding aims to encode the low entropy data so that it can be compressed more efficiently. For <code class="language-plaintext highlighter-rouge">roooar</code> you
will need 6 bytes of data but with assigning codes you can use fewer bytes, for example you could assign the following
bits to the letters:</p>

<table>
  <thead>
    <tr>
      <th>Character</th>
      <th>Bits</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>r</td>
      <td>100</td>
    </tr>
    <tr>
      <td>o</td>
      <td>0</td>
    </tr>
    <tr>
      <td>a</td>
      <td>101</td>
    </tr>
  </tbody>
</table>

<p>That will yield something like: 100,0,0,0,101,100, which represents roar using only 12 bits, which means that you’ve
compressed the word <code class="language-plaintext highlighter-rouge">roooar</code> from 6 bytes to 2 bytes. You will need to pad those 12 bits to that you’ll end up with 16
bits, two bytes.</p>

<p>If you want to implement Huffman trees by yourself scroll down to the References section and check out the links. Next
I will show and discuss with you my Python based implementation.</p>

<h1 id="implementing-a-compression-tool">Implementing a Compression tool</h1>

<p>Let’s walk through a Python tool that compresses data using Huffman coding trees. The full implementation
can be found on my Github and self-hosted Gitlab accounts.</p>

<ul>
  <li><a href="https://github.com/dnutiu/huffman-trees">https://github.com/dnutiu/huffman-trees</a></li>
  <li><a href="https://gitlab.nuculabs.dev/dnutiu/huffmantrees">https://gitlab.nuculabs.dev/dnutiu/huffmantrees</a></li>
</ul>

<h2 id="frequency-map">Frequency Map</h2>

<p>The first step is to create a frequency map, you need to count the number of characters in the source file in order
to determine the characters and bytes which occur more often.</p>

<p>In Python, you can create a frequency map by waking through the bytes of the file and counting the occurrences of
each byte.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line">    <span class="k">def</span> <span class="nf">_build_frequency_map</span><span class="p">(</span><span class="n">self</span><span class="p">,</span> <span class="n">content</span><span class="p">:</span> <span class="nb">bytes</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">dict</span><span class="p">[</span><span class="nb">int</span><span class="p">,</span> <span class="nb">int</span><span class="p">]:</span></span><span class="code-line">        <span class="sh">"""</span></span><span class="code-line"><span class="s">            Build the frequency map by counting how many times each byte appears in the content. </span></span><span class="code-line"><span class="s">        :param content: The source content bytes.</span></span><span class="code-line"><span class="s">        :return: A frequency map dictionary.</span></span><span class="code-line"><span class="s">        </span><span class="sh">"""</span></span><span class="code-line">        <span class="k">with</span> <span class="n">utils</span><span class="p">.</span><span class="nc">Timer</span><span class="p">(</span><span class="n">name</span><span class="o">=</span><span class="sh">"</span><span class="s">Build frequency map</span><span class="sh">"</span><span class="p">,</span> <span class="n">logger</span><span class="o">=</span><span class="n">self</span><span class="p">.</span><span class="n">_logger</span><span class="p">):</span></span><span class="code-line">            <span class="n">frequency_map</span> <span class="o">=</span> <span class="nf">defaultdict</span><span class="p">(</span><span class="k">lambda</span><span class="p">:</span> <span class="mi">0</span><span class="p">)</span></span><span class="code-line">            <span class="k">for</span> <span class="n">byte</span> <span class="ow">in</span> <span class="n">content</span><span class="p">:</span></span><span class="code-line">                <span class="n">frequency_map</span><span class="p">[</span><span class="n">byte</span><span class="p">]</span> <span class="o">+=</span> <span class="mi">1</span></span><span class="code-line">            <span class="k">return</span> <span class="n">frequency_map</span></span></code></pre></div></div>

<p>I think this part is quite straight forward to understand, next we’ll use the frequency map by building the tree.</p>

<h2 id="building-the-tree">Building the tree</h2>

<p>The Huffman tree has two types of nodes, internal node and leaf node. We’re currently only interested in leaf nodes and
we use the internal nodes to traverse the tree in order to get the final encoding.</p>

<p>The strategy is to create a leaf node from each byte and assign it a weight which is equal to it’s frequency. 
After that we take two items (leaf or internal node) with the minimum weight and build an internal node, to which we 
assign the weight as a sum of the two nodes we just took.</p>

<p>To build this efficiently we can use a min heap or a min priority queue. If you want to keep it simple you can also put 
all the leaf nodes in an array, and create a function that returns and removes the item with the minimum weight. 
You’d use that function recursively to grab two items at a time, build an internal node and put back the internal node 
in the array, by doing this over and over you’ll end up with a single element in the array, which is the root node.</p>

<p>In my implementation I’ve used a min heal to efficiently search the minimum element and build the tree.</p>

<p>In the following snippet, I’ve included the whole tree source code:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="kn">import</span> <span class="n">abc</span></span><span class="code-line"><span class="kn">import</span> <span class="n">heapq</span></span><span class="code-line"><span class="kn">import</span> <span class="n">typing</span></span><span class="code-line"><span class="kn">from</span> <span class="n">functools</span> <span class="kn">import</span> <span class="n">total_ordering</span></span><span class="code-line"></span><span class="code-line"></span><span class="code-line"><span class="k">class</span> <span class="nc">BaseTreeNode</span><span class="p">(</span><span class="n">abc</span><span class="p">.</span><span class="n">ABC</span><span class="p">):</span></span><span class="code-line">    <span class="sh">"""</span></span><span class="code-line"><span class="s">    Abstract base tree class that models a huffman tree.</span></span><span class="code-line"><span class="s">    </span><span class="sh">"""</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">__init__</span><span class="p">(</span><span class="n">self</span><span class="p">,</span> <span class="n">weight</span><span class="p">:</span> <span class="nb">int</span><span class="p">,</span> <span class="n">is_leaf</span><span class="p">:</span> <span class="nb">bool</span> <span class="o">=</span> <span class="bp">False</span><span class="p">):</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_weight</span><span class="p">:</span> <span class="nb">int</span> <span class="o">=</span> <span class="n">weight</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_is_leaf</span><span class="p">:</span> <span class="nb">bool</span> <span class="o">=</span> <span class="n">is_leaf</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">weight</span><span class="p">(</span><span class="n">self</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">int</span><span class="p">:</span></span><span class="code-line">        <span class="k">return</span> <span class="n">self</span><span class="p">.</span><span class="n">_weight</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">is_leaf</span><span class="p">(</span><span class="n">self</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">bool</span><span class="p">:</span></span><span class="code-line">        <span class="k">return</span> <span class="n">self</span><span class="p">.</span><span class="n">_is_leaf</span></span><span class="code-line"></span><span class="code-line"></span><span class="code-line"><span class="nd">@total_ordering</span></span><span class="code-line"><span class="k">class</span> <span class="nc">LeafNode</span><span class="p">(</span><span class="n">BaseTreeNode</span><span class="p">):</span></span><span class="code-line">    <span class="k">def</span> <span class="nf">__init__</span><span class="p">(</span><span class="n">self</span><span class="p">,</span> <span class="n">byte_element</span><span class="p">:</span> <span class="nb">int</span><span class="p">,</span> <span class="n">weight</span><span class="p">:</span> <span class="nb">int</span><span class="p">):</span></span><span class="code-line">        <span class="nf">super</span><span class="p">().</span><span class="nf">__init__</span><span class="p">(</span><span class="n">weight</span><span class="p">,</span> <span class="n">is_leaf</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_element</span><span class="p">:</span> <span class="nb">int</span> <span class="o">=</span> <span class="n">byte_element</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">value</span><span class="p">(</span><span class="n">self</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">int</span><span class="p">:</span></span><span class="code-line">        <span class="k">return</span> <span class="n">self</span><span class="p">.</span><span class="n">_element</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">__lt__</span><span class="p">(</span><span class="n">self</span><span class="p">,</span> <span class="n">other</span><span class="p">):</span></span><span class="code-line">        <span class="k">if</span> <span class="ow">not</span> <span class="nf">issubclass</span><span class="p">(</span><span class="n">other</span><span class="p">.</span><span class="n">__class__</span><span class="p">,</span> <span class="n">BaseTreeNode</span><span class="p">):</span></span><span class="code-line">            <span class="k">return</span> <span class="nb">NotImplemented</span></span><span class="code-line">        <span class="k">return</span> <span class="n">self</span><span class="p">.</span><span class="nf">weight</span><span class="p">()</span> <span class="o">&lt;</span> <span class="n">other</span><span class="p">.</span><span class="nf">weight</span><span class="p">()</span></span><span class="code-line"></span><span class="code-line"></span><span class="code-line"><span class="k">class</span> <span class="nc">InternalNode</span><span class="p">(</span><span class="n">BaseTreeNode</span><span class="p">):</span></span><span class="code-line">    <span class="k">def</span> <span class="nf">__init__</span><span class="p">(</span><span class="n">self</span><span class="p">,</span> <span class="n">left</span><span class="p">:</span> <span class="n">BaseTreeNode</span><span class="p">,</span> <span class="n">right</span><span class="p">:</span> <span class="n">BaseTreeNode</span><span class="p">):</span></span><span class="code-line">        <span class="n">weight</span> <span class="o">=</span> <span class="n">left</span><span class="p">.</span><span class="nf">weight</span><span class="p">()</span> <span class="o">+</span> <span class="n">right</span><span class="p">.</span><span class="nf">weight</span><span class="p">()</span></span><span class="code-line">        <span class="nf">super</span><span class="p">().</span><span class="nf">__init__</span><span class="p">(</span><span class="n">weight</span><span class="p">,</span> <span class="n">is_leaf</span><span class="o">=</span><span class="bp">False</span><span class="p">)</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_weight</span> <span class="o">=</span> <span class="n">weight</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_left</span> <span class="o">=</span> <span class="n">left</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_right</span> <span class="o">=</span> <span class="n">right</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">left</span><span class="p">(</span><span class="n">self</span><span class="p">):</span></span><span class="code-line">        <span class="k">return</span> <span class="n">self</span><span class="p">.</span><span class="n">_left</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">right</span><span class="p">(</span><span class="n">self</span><span class="p">):</span></span><span class="code-line">        <span class="k">return</span> <span class="n">self</span><span class="p">.</span><span class="n">_right</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">__lt__</span><span class="p">(</span><span class="n">self</span><span class="p">,</span> <span class="n">other</span><span class="p">):</span></span><span class="code-line">        <span class="k">if</span> <span class="ow">not</span> <span class="nf">issubclass</span><span class="p">(</span><span class="n">other</span><span class="p">.</span><span class="n">__class__</span><span class="p">,</span> <span class="n">BaseTreeNode</span><span class="p">):</span></span><span class="code-line">            <span class="k">return</span> <span class="nb">NotImplemented</span></span><span class="code-line">        <span class="k">return</span> <span class="n">self</span><span class="p">.</span><span class="nf">weight</span><span class="p">()</span> <span class="o">&lt;</span> <span class="n">other</span><span class="p">.</span><span class="nf">weight</span><span class="p">()</span></span><span class="code-line"></span><span class="code-line">    <span class="nd">@staticmethod</span></span><span class="code-line">    <span class="k">def</span> <span class="nf">from_frequency_map</span><span class="p">(</span></span><span class="code-line">        <span class="n">frequency_map</span><span class="p">:</span> <span class="nb">dict</span><span class="p">[</span><span class="nb">int</span><span class="p">,</span> <span class="nb">int</span><span class="p">],</span></span><span class="code-line">    <span class="p">)</span> <span class="o">-&gt;</span> <span class="n">typing</span><span class="p">.</span><span class="n">Optional</span><span class="p">[</span><span class="sh">"</span><span class="s">InternalNode</span><span class="sh">"</span><span class="p">]:</span></span><span class="code-line">        <span class="sh">"""</span></span><span class="code-line"><span class="s">            Builds the huffman tree from a given frequency map.</span></span><span class="code-line"><span class="s">        :param frequency_map: The frequency map.</span></span><span class="code-line"><span class="s">        :return: An internal node representing the root of the tree.</span></span><span class="code-line"><span class="s">        </span><span class="sh">"""</span></span><span class="code-line">        <span class="k">if</span> <span class="ow">not</span> <span class="n">frequency_map</span><span class="p">:</span></span><span class="code-line">            <span class="k">return</span> <span class="bp">None</span></span><span class="code-line">        <span class="c1"># Create a heap</span></span><span class="code-line">        <span class="n">binary_heap</span> <span class="o">=</span> <span class="p">[]</span></span><span class="code-line">        <span class="k">for</span> <span class="n">item</span> <span class="ow">in</span> <span class="n">frequency_map</span><span class="p">.</span><span class="nf">items</span><span class="p">():</span></span><span class="code-line">            <span class="c1"># push item into the heap by frequency and character</span></span><span class="code-line">            <span class="n">heapq</span><span class="p">.</span><span class="nf">heappush</span><span class="p">(</span><span class="n">binary_heap</span><span class="p">,</span> <span class="nc">LeafNode</span><span class="p">(</span><span class="n">byte_element</span><span class="o">=</span><span class="n">item</span><span class="p">[</span><span class="mi">0</span><span class="p">],</span> <span class="n">weight</span><span class="o">=</span><span class="n">item</span><span class="p">[</span><span class="mi">1</span><span class="p">]))</span></span><span class="code-line"></span><span class="code-line">        <span class="c1"># Build the Huffman tree</span></span><span class="code-line">        <span class="k">while</span> <span class="nf">len</span><span class="p">(</span><span class="n">binary_heap</span><span class="p">)</span> <span class="o">&gt;</span> <span class="mi">1</span><span class="p">:</span></span><span class="code-line">            <span class="n">left</span> <span class="o">=</span> <span class="n">heapq</span><span class="p">.</span><span class="nf">heappop</span><span class="p">(</span><span class="n">binary_heap</span><span class="p">)</span></span><span class="code-line">            <span class="n">right</span> <span class="o">=</span> <span class="n">heapq</span><span class="p">.</span><span class="nf">heappop</span><span class="p">(</span><span class="n">binary_heap</span><span class="p">)</span></span><span class="code-line">            <span class="c1">#  internal node by frequency, in order to be traversed</span></span><span class="code-line">            <span class="n">heapq</span><span class="p">.</span><span class="nf">heappush</span><span class="p">(</span><span class="n">binary_heap</span><span class="p">,</span> <span class="nc">InternalNode</span><span class="p">(</span><span class="n">left</span><span class="p">,</span> <span class="n">right</span><span class="p">))</span></span><span class="code-line">        <span class="k">return</span> <span class="n">binary_heap</span><span class="p">[</span><span class="mi">0</span><span class="p">]</span></span></code></pre></div></div>

<h2 id="creating-the-encodings">Creating the encodings</h2>

<p>You will need to traverse the tree in order to build the encoding table or grab the encoding for a single character. 
In order to avoid duplicate work I’ve decided to traverse the tree once and build the encoding table in one shot.</p>

<p>To traverse the tree you can use a DFS (Depth First Search) algorithm. It work by going in depth to each leaf node. 
Once you hit the leaf node you save the value to a map and the path taken to get there, if you’ve traversed the tree 
left you’d usually put a 0 and if you’ve traverse the tree right you can put a 1.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line">    <span class="k">def</span> <span class="nf">_build_encoding_table</span><span class="p">(</span><span class="n">self</span><span class="p">):</span></span><span class="code-line">        <span class="sh">"""</span></span><span class="code-line"><span class="s">        Builds the encoding table for huffman using a Depth First Search algorithm on the tree.</span></span><span class="code-line"><span class="s">        </span><span class="sh">"""</span></span><span class="code-line">        <span class="k">with</span> <span class="n">utils</span><span class="p">.</span><span class="nc">Timer</span><span class="p">(</span><span class="n">name</span><span class="o">=</span><span class="sh">"</span><span class="s">Build encoding table</span><span class="sh">"</span><span class="p">,</span> <span class="n">logger</span><span class="o">=</span><span class="n">self</span><span class="p">.</span><span class="n">_logger</span><span class="p">):</span></span><span class="code-line">            <span class="n">stack</span> <span class="o">=</span> <span class="p">[]</span></span><span class="code-line">            <span class="n">root</span> <span class="o">=</span> <span class="n">self</span><span class="p">.</span><span class="n">_huffman_tree_root</span></span><span class="code-line">            <span class="n">stack</span><span class="p">.</span><span class="nf">append</span><span class="p">([</span><span class="n">root</span><span class="p">,</span> <span class="p">[]])</span></span><span class="code-line">            <span class="k">while</span> <span class="nf">len</span><span class="p">(</span><span class="n">stack</span><span class="p">)</span> <span class="o">&gt;</span> <span class="mi">0</span><span class="p">:</span></span><span class="code-line">                <span class="n">element</span><span class="p">,</span> <span class="n">encoding</span> <span class="o">=</span> <span class="n">stack</span><span class="p">.</span><span class="nf">pop</span><span class="p">()</span></span><span class="code-line">                <span class="k">if</span> <span class="n">element</span><span class="p">.</span><span class="nf">is_leaf</span><span class="p">():</span></span><span class="code-line">                    <span class="n">self</span><span class="p">.</span><span class="n">_encoding_table</span><span class="p">[</span><span class="n">element</span><span class="p">.</span><span class="nf">value</span><span class="p">()]</span> <span class="o">=</span> <span class="sh">""</span><span class="p">.</span><span class="nf">join</span><span class="p">(</span><span class="n">encoding</span><span class="p">)</span></span><span class="code-line">                <span class="k">else</span><span class="p">:</span></span><span class="code-line">                    <span class="nf">if </span><span class="p">(</span><span class="n">left</span> <span class="p">:</span><span class="o">=</span> <span class="n">element</span><span class="p">.</span><span class="nf">left</span><span class="p">())</span> <span class="ow">is</span> <span class="ow">not</span> <span class="bp">None</span><span class="p">:</span></span><span class="code-line">                        <span class="n">stack</span><span class="p">.</span><span class="nf">append</span><span class="p">([</span><span class="n">left</span><span class="p">,</span> <span class="p">[</span><span class="o">*</span><span class="n">encoding</span><span class="p">,</span> <span class="sh">"</span><span class="s">0</span><span class="sh">"</span><span class="p">]])</span></span><span class="code-line">                    <span class="nf">if </span><span class="p">(</span><span class="n">right</span> <span class="p">:</span><span class="o">=</span> <span class="n">element</span><span class="p">.</span><span class="nf">right</span><span class="p">())</span> <span class="ow">is</span> <span class="ow">not</span> <span class="bp">None</span><span class="p">:</span></span><span class="code-line">                        <span class="n">stack</span><span class="p">.</span><span class="nf">append</span><span class="p">([</span><span class="n">right</span><span class="p">,</span> <span class="p">[</span><span class="o">*</span><span class="n">encoding</span><span class="p">,</span> <span class="sh">"</span><span class="s">1</span><span class="sh">"</span><span class="p">]])</span></span></code></pre></div></div>

<h2 id="writing-to-the-file">Writing to the file</h2>

<p>Writing to the file is the tricky part, because since you’re encoding each element into a bit sequence you will need
to pad the final amount of bits such that it is divisible by 8, and you can only write 8 bits (a byte) at a time. You
can’t write <code class="language-plaintext highlighter-rouge">111</code> for example, you have to write the whole byte with padding <code class="language-plaintext highlighter-rouge">11100000</code>. I’ve used the <code class="language-plaintext highlighter-rouge">bitstring</code>
Python package to simplify this process and at the end I’ve added the padding manually.</p>

<p>Besides writing the content you need to write the encoding table in the file as well. It will be used to decode the
file. To write the encoding table I have used Python’s built-in package <code class="language-plaintext highlighter-rouge">pickle</code> but you can use a 3rd party library
such as msgpack to convert the object to binary form. You could also write it as a simple string.</p>

<p>I’ve written the encoding table at the beginning and it’s length so that I know that the rest of the bytes are the
file’s content.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line">    <span class="k">def</span> <span class="nf">_get_encoded_file_contents</span><span class="p">(</span><span class="n">self</span><span class="p">,</span> <span class="n">content</span><span class="p">:</span> <span class="nb">bytes</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="n">BitArray</span><span class="p">:</span></span><span class="code-line">        <span class="sh">"""</span></span><span class="code-line"><span class="s">            Given unencoded contents it encodes them with huffman codes.</span></span><span class="code-line"><span class="s">        :param content: The raw content bytes.</span></span><span class="code-line"><span class="s">        :return: The encoded content bytes.</span></span><span class="code-line"><span class="s">        </span><span class="sh">"""</span></span><span class="code-line">        <span class="k">with</span> <span class="n">utils</span><span class="p">.</span><span class="nc">Timer</span><span class="p">(</span><span class="n">name</span><span class="o">=</span><span class="sh">"</span><span class="s">Encode source file</span><span class="sh">"</span><span class="p">,</span> <span class="n">logger</span><span class="o">=</span><span class="n">self</span><span class="p">.</span><span class="n">_logger</span><span class="p">):</span></span><span class="code-line">            <span class="nb">buffer</span> <span class="o">=</span> <span class="p">[]</span></span><span class="code-line">            <span class="k">for</span> <span class="n">byte</span> <span class="ow">in</span> <span class="n">content</span><span class="p">:</span></span><span class="code-line">                <span class="nb">buffer</span><span class="p">.</span><span class="nf">append</span><span class="p">(</span><span class="n">self</span><span class="p">.</span><span class="nf">_encode_byte</span><span class="p">(</span><span class="n">byte</span><span class="p">))</span></span><span class="code-line">            <span class="n">bit_array</span> <span class="o">=</span> <span class="nc">BitArray</span><span class="p">(</span><span class="nb">bin</span><span class="o">=</span><span class="sh">""</span><span class="p">.</span><span class="nf">join</span><span class="p">(</span><span class="nb">buffer</span><span class="p">))</span></span><span class="code-line">            <span class="k">return</span> <span class="n">bit_array</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">_encode_byte</span><span class="p">(</span><span class="n">self</span><span class="p">,</span> <span class="n">byte</span><span class="p">:</span> <span class="nb">int</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">str</span><span class="p">:</span></span><span class="code-line">        <span class="sh">"""</span></span><span class="code-line"><span class="s">        Encode the given byte using the huffman tree.</span></span><span class="code-line"><span class="s">        </span><span class="sh">"""</span></span><span class="code-line">        <span class="k">if</span> <span class="n">byte</span> <span class="ow">in</span> <span class="n">self</span><span class="p">.</span><span class="n">_encoding_table</span><span class="p">:</span></span><span class="code-line">            <span class="k">return</span> <span class="n">self</span><span class="p">.</span><span class="n">_encoding_table</span><span class="p">[</span><span class="n">byte</span><span class="p">]</span></span><span class="code-line">        <span class="k">raise</span> <span class="nc">Exception</span><span class="p">(</span></span><span class="code-line">            <span class="sa">f</span><span class="sh">"</span><span class="s">Can</span><span class="sh">'</span><span class="s">t encode byte </span><span class="si">{</span><span class="n">byte</span><span class="si">}</span><span class="s">. It is not found in the encoding table.</span><span class="sh">"</span></span><span class="code-line">        <span class="p">)</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">encode</span><span class="p">(</span><span class="n">self</span><span class="p">,</span> <span class="n">file_name</span><span class="p">:</span> <span class="nb">str</span><span class="p">,</span> <span class="n">destination</span><span class="p">:</span> <span class="nb">str</span><span class="p">):</span></span><span class="code-line">        <span class="sh">"""</span></span><span class="code-line"><span class="s">            Encodes a given file into huffman bytes and writes it to disk..</span></span><span class="code-line"><span class="s">        :param file_name: The path to the file name.</span></span><span class="code-line"><span class="s">        :param destination: The path to the destination file name.</span></span><span class="code-line"><span class="s">        </span><span class="sh">"""</span></span><span class="code-line">        <span class="k">with</span> <span class="nf">open</span><span class="p">(</span><span class="n">file_name</span><span class="p">,</span> <span class="sh">"</span><span class="s">rb</span><span class="sh">"</span><span class="p">)</span> <span class="k">as</span> <span class="n">fh</span><span class="p">:</span></span><span class="code-line">            <span class="n">content</span> <span class="o">=</span> <span class="n">fh</span><span class="p">.</span><span class="nf">read</span><span class="p">()</span></span><span class="code-line"></span><span class="code-line">        <span class="n">frequency_map</span> <span class="o">=</span> <span class="n">self</span><span class="p">.</span><span class="nf">_build_frequency_map</span><span class="p">(</span><span class="n">content</span><span class="p">)</span></span><span class="code-line"></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="nf">_build_huffman_tree</span><span class="p">(</span><span class="n">frequency_map</span><span class="p">)</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="nf">_build_encoding_table</span><span class="p">()</span></span><span class="code-line"></span><span class="code-line">        <span class="n">bit_array</span> <span class="o">=</span> <span class="nc">BitArray</span><span class="p">()</span></span><span class="code-line">        <span class="n">encoding_table</span> <span class="o">=</span> <span class="n">pickle</span><span class="p">.</span><span class="nf">dumps</span><span class="p">(</span><span class="n">self</span><span class="p">.</span><span class="n">_encoding_table</span><span class="p">)</span></span><span class="code-line">        <span class="c1"># 2 bytes unsigned integer for the encoding table length</span></span><span class="code-line">        <span class="n">bit_array</span><span class="p">.</span><span class="nf">append</span><span class="p">(</span><span class="nf">pack</span><span class="p">(</span><span class="sh">"</span><span class="s">&lt;H</span><span class="sh">"</span><span class="p">,</span> <span class="nf">len</span><span class="p">(</span><span class="n">encoding_table</span><span class="p">)))</span></span><span class="code-line">        <span class="c1"># the whole encoding table pickled</span></span><span class="code-line">        <span class="n">bit_array</span><span class="p">.</span><span class="nf">append</span><span class="p">(</span><span class="n">encoding_table</span><span class="p">)</span></span><span class="code-line">        <span class="c1"># the huffman encoded file contents</span></span><span class="code-line">        <span class="n">encoded_content</span> <span class="o">=</span> <span class="n">self</span><span class="p">.</span><span class="nf">_get_encoded_file_contents</span><span class="p">(</span><span class="n">content</span><span class="p">)</span></span><span class="code-line">        <span class="k">if</span> <span class="nf">len</span><span class="p">(</span><span class="n">encoded_content</span><span class="p">)</span> <span class="o">%</span> <span class="mi">8</span> <span class="o">==</span> <span class="mi">0</span><span class="p">:</span></span><span class="code-line">            <span class="n">encoded_content_padding_bits</span> <span class="o">=</span> <span class="mi">0</span></span><span class="code-line">        <span class="k">else</span><span class="p">:</span></span><span class="code-line">            <span class="n">encoded_content_padding_bits</span> <span class="o">=</span> <span class="mi">8</span> <span class="o">-</span> <span class="p">(</span><span class="nf">len</span><span class="p">(</span><span class="n">encoded_content</span><span class="p">)</span> <span class="o">%</span> <span class="mi">8</span><span class="p">)</span></span><span class="code-line">        <span class="n">bit_array</span><span class="p">.</span><span class="nf">append</span><span class="p">(</span><span class="nf">pack</span><span class="p">(</span><span class="sh">"</span><span class="s">&lt;B</span><span class="sh">"</span><span class="p">,</span> <span class="n">encoded_content_padding_bits</span><span class="p">))</span></span><span class="code-line">        <span class="n">bit_array</span><span class="p">.</span><span class="nf">append</span><span class="p">(</span><span class="n">encoded_content</span><span class="p">)</span></span><span class="code-line"></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="nf">_write_to_destination_file</span><span class="p">(</span><span class="n">bit_array</span><span class="p">,</span> <span class="n">destination</span><span class="p">)</span></span><span class="code-line">        <span class="n">self</span><span class="p">.</span><span class="n">_logger</span><span class="p">.</span><span class="nf">info</span><span class="p">(</span><span class="sa">f</span><span class="sh">"</span><span class="s">Done encoding </span><span class="si">{</span><span class="n">file_name</span><span class="si">}</span><span class="s">.</span><span class="sh">"</span><span class="p">)</span></span><span class="code-line"></span><span class="code-line"><span class="c1">#...</span></span><span class="code-line"></span><span class="code-line">    <span class="k">def</span> <span class="nf">_write_to_destination_file</span><span class="p">(</span><span class="n">self</span><span class="p">,</span> <span class="n">content</span><span class="p">:</span> <span class="n">BitArray</span><span class="p">,</span> <span class="n">destination</span><span class="p">:</span> <span class="nb">str</span><span class="p">):</span></span><span class="code-line">        <span class="sh">"""</span></span><span class="code-line"><span class="s">            Writes the bytes to the destination file.</span></span><span class="code-line"><span class="s">        :param content: The content bytes.</span></span><span class="code-line"><span class="s">        :param destination: The destination file name</span></span><span class="code-line"><span class="s">        </span><span class="sh">"""</span></span><span class="code-line">        <span class="k">with</span> <span class="n">utils</span><span class="p">.</span><span class="nc">Timer</span><span class="p">(</span><span class="n">name</span><span class="o">=</span><span class="sh">"</span><span class="s">Write to destination</span><span class="sh">"</span><span class="p">,</span> <span class="n">logger</span><span class="o">=</span><span class="n">self</span><span class="p">.</span><span class="n">_logger</span><span class="p">):</span></span><span class="code-line">            <span class="k">with</span> <span class="nf">open</span><span class="p">(</span><span class="n">destination</span><span class="p">,</span> <span class="sh">"</span><span class="s">wb</span><span class="sh">"</span><span class="p">)</span> <span class="k">as</span> <span class="n">fh</span><span class="p">:</span></span><span class="code-line">                <span class="n">content</span><span class="p">.</span><span class="nf">tofile</span><span class="p">(</span><span class="n">fh</span><span class="p">)</span></span><span class="code-line">            <span class="n">self</span><span class="p">.</span><span class="n">_logger</span><span class="p">.</span><span class="nf">debug</span><span class="p">(</span></span><span class="code-line">                <span class="sa">f</span><span class="sh">"</span><span class="s">Wrote </span><span class="si">{</span><span class="n">content</span><span class="p">.</span><span class="nb">len</span><span class="si">}</span><span class="s"> bits to destination file: </span><span class="si">{</span><span class="n">destination</span><span class="si">}</span><span class="sh">"</span></span><span class="code-line">            <span class="p">)</span></span></code></pre></div></div>

<h2 id="decompressing">Decompressing</h2>

<p>Decompressing the file is a straight forward step. You can read the encoding table, reverse it, build a map and retrieve
the original elements from there, then write the bytes to the output file.</p>

<h1 id="conclusion">Conclusion</h1>

<p>The Huffman project is an interesting project, it touches algorithms, bit manipulations, files, io, and it is used
in many real life applications as well, and formats. If you try to compress a PNG with it, it won’t work because
compressing it twice doesn’t yield better results.</p>

<p>If you want to implement it yourself, give it a try. Bellow you can find my Python implementation and some reffereces
that I’ve used to implement it.</p>

<p>Thanks for reading!</p>

<h1 id="references">References</h1>

<ul>
  <li><a href="https://en.wikipedia.org/wiki/Entropy_(computing)">https://en.wikipedia.org/wiki/Entropy_(computing)</a></li>
  <li><a href="https://en.wikipedia.org/wiki/Entropy_coding">https://en.wikipedia.org/wiki/Entropy_coding</a></li>
  <li><a href="https://codingchallenges.fyi/challenges/challenge-huffman/">https://codingchallenges.fyi/challenges/challenge-huffman/</a></li>
  <li><a href="https://opendsa-server.cs.vt.edu/ODSA/Books/CS3/html/Huffman.html">https://opendsa-server.cs.vt.edu/ODSA/Books/CS3/html/Huffman.html</a></li>
  <li><a href="https://gitlab.nuculabs.dev/dnutiu/huffmantreespy/">https://gitlab.nuculabs.dev/dnutiu/huffmantreespy/</a></li>
  <li><a href="https://github.com/dnutiu/huffman-trees">https://github.com/dnutiu/huffman-trees</a></li>
</ul>]]></content><author><name>Denis</name></author><category term="Programming" /><category term="Python" /><category term="Data Structures &amp; Algorithms" /><category term="Featured" /><category term="ruby" /><category term="programming" /><summary type="html"><![CDATA[Hello everyone! 👋 This article is about Huffman Trees, I did this project in university and after ten years or so I wanted to revisit it in order to solidify my understanding and to practice manual coding. Introduction The Huffman coding tree is a fundamental data structure in computer science, and it is used for lossless data compression and entropy coding. Huffman coding trees are already used in ZIP, Mp3, Png for compression often not alone but with other data compression algorithms. Entropy represents the randomness of the data. Say roooar, it has 6 characters length and there are 3 unique characters, the entropy is low because of the repeating characters, which implies less uncertainty. For 123456, there are 6 characters and 6 unique characters, the entropy is high because the data looks “random”, there is more uncertainty. Entropy coding aims to encode the low entropy data so that it can be compressed more efficiently. For roooar you will need 6 bytes of data but with assigning codes you can use fewer bytes, for example you could assign the following bits to the letters: Character Bits r 100 o 0 a 101 That will yield something like: 100,0,0,0,101,100, which represents roar using only 12 bits, which means that you’ve compressed the word roooar from 6 bytes to 2 bytes. You will need to pad those 12 bits to that you’ll end up with 16 bits, two bytes. If you want to implement Huffman trees by yourself scroll down to the References section and check out the links. Next I will show and discuss with you my Python based implementation. Implementing a Compression tool Let’s walk through a Python tool that compresses data using Huffman coding trees. The full implementation can be found on my Github and self-hosted Gitlab accounts. https://github.com/dnutiu/huffman-trees https://gitlab.nuculabs.dev/dnutiu/huffmantrees Frequency Map The first step is to create a frequency map, you need to count the number of characters in the source file in order to determine the characters and bytes which occur more often. In Python, you can create a frequency map by waking through the bytes of the file and counting the occurrences of each byte. def _build_frequency_map(self, content: bytes) -&gt; dict[int, int]: """ Build the frequency map by counting how many times each byte appears in the content. :param content: The source content bytes. :return: A frequency map dictionary. """ with utils.Timer(name="Build frequency map", logger=self._logger): frequency_map = defaultdict(lambda: 0) for byte in content: frequency_map[byte] += 1 return frequency_map I think this part is quite straight forward to understand, next we’ll use the frequency map by building the tree. Building the tree The Huffman tree has two types of nodes, internal node and leaf node. We’re currently only interested in leaf nodes and we use the internal nodes to traverse the tree in order to get the final encoding. The strategy is to create a leaf node from each byte and assign it a weight which is equal to it’s frequency. After that we take two items (leaf or internal node) with the minimum weight and build an internal node, to which we assign the weight as a sum of the two nodes we just took. To build this efficiently we can use a min heap or a min priority queue. If you want to keep it simple you can also put all the leaf nodes in an array, and create a function that returns and removes the item with the minimum weight. You’d use that function recursively to grab two items at a time, build an internal node and put back the internal node in the array, by doing this over and over you’ll end up with a single element in the array, which is the root node. In my implementation I’ve used a min heal to efficiently search the minimum element and build the tree. In the following snippet, I’ve included the whole tree source code: import abcimport heapqimport typingfrom functools import total_orderingclass BaseTreeNode(abc.ABC): """ Abstract base tree class that models a huffman tree. """ def __init__(self, weight: int, is_leaf: bool = False): self._weight: int = weight self._is_leaf: bool = is_leaf def weight(self) -&gt; int: return self._weight def is_leaf(self) -&gt; bool: return self._is_leaf@total_orderingclass LeafNode(BaseTreeNode): def __init__(self, byte_element: int, weight: int): super().__init__(weight, is_leaf=True) self._element: int = byte_element def value(self) -&gt; int: return self._element def __lt__(self, other): if not issubclass(other.__class__, BaseTreeNode): return NotImplemented return self.weight() &lt; other.weight()class InternalNode(BaseTreeNode): def __init__(self, left: BaseTreeNode, right: BaseTreeNode): weight = left.weight() + right.weight() super().__init__(weight, is_leaf=False) self._weight = weight self._left = left self._right = right def left(self): return self._left def right(self): return self._right def __lt__(self, other): if not issubclass(other.__class__, BaseTreeNode): return NotImplemented return self.weight() &lt; other.weight() @staticmethod def from_frequency_map( frequency_map: dict[int, int], ) -&gt; typing.Optional["InternalNode"]: """ Builds the huffman tree from a given frequency map. :param frequency_map: The frequency map. :return: An internal node representing the root of the tree. """ if not frequency_map: return None # Create a heap binary_heap = [] for item in frequency_map.items(): # push item into the heap by frequency and character heapq.heappush(binary_heap, LeafNode(byte_element=item[0], weight=item[1])) # Build the Huffman tree while len(binary_heap) &gt; 1: left = heapq.heappop(binary_heap) right = heapq.heappop(binary_heap) # internal node by frequency, in order to be traversed heapq.heappush(binary_heap, InternalNode(left, right)) return binary_heap[0] Creating the encodings You will need to traverse the tree in order to build the encoding table or grab the encoding for a single character. In order to avoid duplicate work I’ve decided to traverse the tree once and build the encoding table in one shot. To traverse the tree you can use a DFS (Depth First Search) algorithm. It work by going in depth to each leaf node. Once you hit the leaf node you save the value to a map and the path taken to get there, if you’ve traversed the tree left you’d usually put a 0 and if you’ve traverse the tree right you can put a 1. def _build_encoding_table(self): """ Builds the encoding table for huffman using a Depth First Search algorithm on the tree. """ with utils.Timer(name="Build encoding table", logger=self._logger): stack = [] root = self._huffman_tree_root stack.append([root, []]) while len(stack) &gt; 0: element, encoding = stack.pop() if element.is_leaf(): self._encoding_table[element.value()] = "".join(encoding) else: if (left := element.left()) is not None: stack.append([left, [*encoding, "0"]]) if (right := element.right()) is not None: stack.append([right, [*encoding, "1"]]) Writing to the file Writing to the file is the tricky part, because since you’re encoding each element into a bit sequence you will need to pad the final amount of bits such that it is divisible by 8, and you can only write 8 bits (a byte) at a time. You can’t write 111 for example, you have to write the whole byte with padding 11100000. I’ve used the bitstring Python package to simplify this process and at the end I’ve added the padding manually. Besides writing the content you need to write the encoding table in the file as well. It will be used to decode the file. To write the encoding table I have used Python’s built-in package pickle but you can use a 3rd party library such as msgpack to convert the object to binary form. You could also write it as a simple string. I’ve written the encoding table at the beginning and it’s length so that I know that the rest of the bytes are the file’s content. def _get_encoded_file_contents(self, content: bytes) -&gt; BitArray: """ Given unencoded contents it encodes them with huffman codes. :param content: The raw content bytes. :return: The encoded content bytes. """ with utils.Timer(name="Encode source file", logger=self._logger): buffer = [] for byte in content: buffer.append(self._encode_byte(byte)) bit_array = BitArray(bin="".join(buffer)) return bit_array def _encode_byte(self, byte: int) -&gt; str: """ Encode the given byte using the huffman tree. """ if byte in self._encoding_table: return self._encoding_table[byte] raise Exception( f"Can't encode byte {byte}. It is not found in the encoding table." ) def encode(self, file_name: str, destination: str): """ Encodes a given file into huffman bytes and writes it to disk.. :param file_name: The path to the file name. :param destination: The path to the destination file name. """ with open(file_name, "rb") as fh: content = fh.read() frequency_map = self._build_frequency_map(content) self._build_huffman_tree(frequency_map) self._build_encoding_table() bit_array = BitArray() encoding_table = pickle.dumps(self._encoding_table) # 2 bytes unsigned integer for the encoding table length bit_array.append(pack("&lt;H", len(encoding_table))) # the whole encoding table pickled bit_array.append(encoding_table) # the huffman encoded file contents encoded_content = self._get_encoded_file_contents(content) if len(encoded_content) % 8 == 0: encoded_content_padding_bits = 0 else: encoded_content_padding_bits = 8 - (len(encoded_content) % 8) bit_array.append(pack("&lt;B", encoded_content_padding_bits)) bit_array.append(encoded_content) self._write_to_destination_file(bit_array, destination) self._logger.info(f"Done encoding {file_name}.")#... def _write_to_destination_file(self, content: BitArray, destination: str): """ Writes the bytes to the destination file. :param content: The content bytes. :param destination: The destination file name """ with utils.Timer(name="Write to destination", logger=self._logger): with open(destination, "wb") as fh: content.tofile(fh) self._logger.debug( f"Wrote {content.len} bits to destination file: {destination}" ) Decompressing Decompressing the file is a straight forward step. You can read the encoding table, reverse it, build a map and retrieve the original elements from there, then write the bytes to the output file. Conclusion The Huffman project is an interesting project, it touches algorithms, bit manipulations, files, io, and it is used in many real life applications as well, and formats. If you try to compress a PNG with it, it won’t work because compressing it twice doesn’t yield better results. If you want to implement it yourself, give it a try. Bellow you can find my Python implementation and some reffereces that I’ve used to implement it. Thanks for reading! References https://en.wikipedia.org/wiki/Entropy_(computing) https://en.wikipedia.org/wiki/Entropy_coding https://codingchallenges.fyi/challenges/challenge-huffman/ https://opendsa-server.cs.vt.edu/ODSA/Books/CS3/html/Huffman.html https://gitlab.nuculabs.dev/dnutiu/huffmantreespy/ https://github.com/dnutiu/huffman-trees]]></summary></entry><entry><title type="html">I like physical media</title><link href="https://nuculabs.dev/life/2026/07/12/physical-media.html" rel="alternate" type="text/html" title="I like physical media" /><published>2026-07-12T00:00:00+03:00</published><updated>2026-07-12T00:00:00+03:00</updated><id>https://nuculabs.dev/life/2026/07/12/physical-media</id><content type="html" xml:base="https://nuculabs.dev/life/2026/07/12/physical-media.html"><![CDATA[<p>Hi everyone,</p>

<p>I wanted to write some thoughts on the whole physical media things.</p>

<p>After Sony announced that it will end releasing physical games for the Playstation after January 2027 I didn’t realise how much I want physical media.</p>

<p>Last year I’ve purchased a lot of DVDs and some BlueRays with some of my favorite movies, and audio CDs as well. The DVDs don’t have a great quality on today’s screens but BlueRays play just fine. I think it is necesary for us to try to preserve the physical format, at least for movies and audio. Companies can always remove movies from their library and yours too, not only that but they can also censor them, delete certain chapters or scenes and that is because you don’t own the data, you rent it, oh, excuse me you have a “license” to use it.</p>

<p>The audio CDs I’ve bought could be easily ripped and the music transferred to my self hosted cloud library of music, so that I can listen to it at any time and have 100% control of the data.</p>

<p>I personally would like to own my data and my devices, that’s one of the main reasons I use Linux.</p>

<p>For games however the story is a bit different. The Playstation platform is proprietary and that means that your disks run on its software, an online patch can always make the device refuse to play them or to force patch the game files, for censorship or content removal due to licensing.</p>

<p>Physical games are great though, you can share them with friends or resell them if you don’t like them, and consoles like Sony and Nintendo have very strict refund rules, if you buy a game and download it you cannot request a refund. Steam on PC on the other had is a paradise of customer service. You can play the game for 2 hours maximum I think and if 14 days haven’t passed you can request a refund and they refund you the full amount.</p>

<p>I think the advantage of owning a PS vs a PC is quite small nowadays. With PlayStation you can play on your TV and have a turn-key gaming setup and that’s okay, but with PC you can do so many other things, and if you invest in a good PC it will last for years, and you can upgrade the parts if you wish. My PC is 5 years old now and I thought about upgrading to add a better CPU, a better graphics card but there’s not reason at all, it works and runs games fine, upgrading it would be wasting money for no reason. I have 64GB RAM which I barely use anyways.</p>

<p>I personally love my Nintendo Switch 2, I can play on TV, on the Go and I can play my favorite game at the moment: Resident Evil Requiem and I’m glad they decided to stick to physical media. Hopefully this won’t change.</p>

<p>Thanks for reading!</p>]]></content><author><name>Denis</name></author><category term="Life" /><category term="life" /><summary type="html"><![CDATA[Hi everyone, I wanted to write some thoughts on the whole physical media things. After Sony announced that it will end releasing physical games for the Playstation after January 2027 I didn’t realise how much I want physical media. Last year I’ve purchased a lot of DVDs and some BlueRays with some of my favorite movies, and audio CDs as well. The DVDs don’t have a great quality on today’s screens but BlueRays play just fine. I think it is necesary for us to try to preserve the physical format, at least for movies and audio. Companies can always remove movies from their library and yours too, not only that but they can also censor them, delete certain chapters or scenes and that is because you don’t own the data, you rent it, oh, excuse me you have a “license” to use it. The audio CDs I’ve bought could be easily ripped and the music transferred to my self hosted cloud library of music, so that I can listen to it at any time and have 100% control of the data. I personally would like to own my data and my devices, that’s one of the main reasons I use Linux. For games however the story is a bit different. The Playstation platform is proprietary and that means that your disks run on its software, an online patch can always make the device refuse to play them or to force patch the game files, for censorship or content removal due to licensing. Physical games are great though, you can share them with friends or resell them if you don’t like them, and consoles like Sony and Nintendo have very strict refund rules, if you buy a game and download it you cannot request a refund. Steam on PC on the other had is a paradise of customer service. You can play the game for 2 hours maximum I think and if 14 days haven’t passed you can request a refund and they refund you the full amount. I think the advantage of owning a PS vs a PC is quite small nowadays. With PlayStation you can play on your TV and have a turn-key gaming setup and that’s okay, but with PC you can do so many other things, and if you invest in a good PC it will last for years, and you can upgrade the parts if you wish. My PC is 5 years old now and I thought about upgrading to add a better CPU, a better graphics card but there’s not reason at all, it works and runs games fine, upgrading it would be wasting money for no reason. I have 64GB RAM which I barely use anyways. I personally love my Nintendo Switch 2, I can play on TV, on the Go and I can play my favorite game at the moment: Resident Evil Requiem and I’m glad they decided to stick to physical media. Hopefully this won’t change. Thanks for reading!]]></summary></entry><entry><title type="html">Loading Ruby files automatically with Zeitwerk</title><link href="https://nuculabs.dev/programming/ruby/2026/06/13/zeitwerk.html" rel="alternate" type="text/html" title="Loading Ruby files automatically with Zeitwerk" /><published>2026-06-13T00:00:00+03:00</published><updated>2026-06-13T00:00:00+03:00</updated><id>https://nuculabs.dev/programming/ruby/2026/06/13/zeitwerk</id><content type="html" xml:base="https://nuculabs.dev/programming/ruby/2026/06/13/zeitwerk.html"><![CDATA[<h1 id="introduction">Introduction</h1>

<p>Hello everyone!</p>

<p>As I was playing around with the Ruby programming language when building a Rails application I came across
<a href="https://github.com/fxn/zeitwerk">Zeitwerk</a>, a library that loads all your ruby files automatically and I wanted to
write about it.</p>

<p>The main idea behind the library is that your projects needs to follow a certain file structure and then the lib
will load all the ruby files, eliminating the necessity to write <code class="language-plaintext highlighter-rouge">require_relative 'x'</code>. This is nice because
it keeps the code structured in an opinionated way and saves some keystrokes from writing import files.</p>

<p>It did confuse me at first when I browsed the source code of <a href="https://gitlab.com/gitlab-org/gitlab">Gitlab</a> 
and I didn’t see any imports, and that is because they use Rails and Zeitwerk.</p>

<h1 id="usage">Usage</h1>

<p>To use the library your project needs to follow the following folder structure:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line">lib/my_gem.rb         -&gt; MyGem</span><span class="code-line">lib/my_gem/foo.rb     -&gt; MyGem::Foo</span><span class="code-line">lib/my_gem/bar_baz.rb -&gt; MyGem::BarBaz</span><span class="code-line">lib/my_gem/woo/zoo.rb -&gt; MyGem::Woo::Zoo</span></code></pre></div></div>

<p>You can also fine tune it by collapsing directories, ignoring directories or adding inflections.
(eg: unicredit.rb to UniCredit, without inflections it would be lowercase <code class="language-plaintext highlighter-rouge">C</code>)</p>

<p>Once you have that structure, you can install it by typing <code class="language-plaintext highlighter-rouge">bundle add zeitwerk</code> and then all you need to do is write
some boilerplate code to set it up.</p>

<h3 id="application">Application</h3>

<p>If you’re writing an application then you can call the library in your main file, specifying which directories
Zeitwerk should load.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="nb">require</span> <span class="s2">"zeitwerk"</span></span><span class="code-line"><span class="c1"># Note: there is no require_relative "huffman" because Zeitwerk loaded it automatically.</span></span><span class="code-line"></span><span class="code-line"><span class="k">def</span> <span class="nf">main</span></span><span class="code-line">  <span class="n">huffman</span> <span class="o">=</span> <span class="no">Huffman</span><span class="p">.</span><span class="nf">new</span><span class="p">(</span><span class="s2">"huffman.md"</span><span class="p">)</span></span><span class="code-line">  <span class="n">content</span> <span class="o">=</span> <span class="n">huffman</span><span class="p">.</span><span class="nf">encode</span></span><span class="code-line">  <span class="nb">print</span> <span class="n">content</span><span class="p">.</span><span class="nf">left</span></span><span class="code-line"><span class="k">end</span></span><span class="code-line"></span><span class="code-line"><span class="k">if</span> <span class="kp">__FILE__</span> <span class="o">==</span> <span class="vg">$0</span></span><span class="code-line">  <span class="c1"># Only three lines of code needed</span></span><span class="code-line">  <span class="n">loader</span> <span class="o">=</span> <span class="no">Zeitwerk</span><span class="o">::</span><span class="no">Loader</span><span class="p">.</span><span class="nf">new</span></span><span class="code-line">  <span class="n">loader</span><span class="p">.</span><span class="nf">push_dir</span><span class="p">(</span><span class="no">File</span><span class="p">.</span><span class="nf">expand_path</span><span class="p">(</span><span class="s2">"./lib"</span><span class="p">))</span></span><span class="code-line">  <span class="n">loader</span><span class="p">.</span><span class="nf">setup</span></span><span class="code-line"></span><span class="code-line">  <span class="n">main</span></span><span class="code-line"><span class="k">end</span></span></code></pre></div></div>

<p>The structure for this application project looks like this:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line">├── Gemfile</span><span class="code-line">├── Gemfile.lock</span><span class="code-line">├── huffman.md</span><span class="code-line">├── lib</span><span class="code-line">│   ├── huffman</span><span class="code-line">│   │   └── base_exception.rb</span><span class="code-line">│   ├── huffman.rb</span><span class="code-line">│   └── tree</span><span class="code-line">│       ├── base_node.rb</span><span class="code-line">│       ├── internal_node.rb</span><span class="code-line">│       └── leaf_node.rb</span><span class="code-line">├── main.rb # The main file, entrypoint</span><span class="code-line">├── Rakefile.rb</span><span class="code-line">└── test</span><span class="code-line">    └── huffman_test.rb</span></code></pre></div></div>

<p>That is basically it.</p>

<h3 id="gem-library">Gem (Library)</h3>

<p>When writing a library gem, you can use <code class="language-plaintext highlighter-rouge">Zeitwerk::Loader.for_gem</code>. In my ExtrasDeCont gem I have the following entrypoint:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="c1"># frozen_string_literal: true</span></span><span class="code-line"><span class="nb">require</span> <span class="s1">'zeitwerk'</span></span><span class="code-line"></span><span class="code-line"><span class="n">loader</span> <span class="o">=</span> <span class="no">Zeitwerk</span><span class="o">::</span><span class="no">Loader</span><span class="p">.</span><span class="nf">for_gem</span></span><span class="code-line"><span class="n">loader</span><span class="p">.</span><span class="nf">inflector</span><span class="p">.</span><span class="nf">inflect</span><span class="p">(</span></span><span class="code-line">  <span class="s2">"unicredit"</span> <span class="o">=&gt;</span> <span class="s2">"UniCredit"</span></span><span class="code-line"><span class="p">)</span></span><span class="code-line"><span class="n">loader</span><span class="p">.</span><span class="nf">setup</span></span><span class="code-line"></span><span class="code-line"><span class="c1"># The ExtrasDeCont module contains utilities for parsing bank statements.</span></span><span class="code-line"><span class="k">module</span> <span class="nn">ExtrasDeCont</span></span><span class="code-line">  <span class="c1"># Map of supported banks (symbol → rule class)</span></span><span class="code-line">  <span class="no">BANK_RULES</span> <span class="o">=</span> <span class="p">{</span></span><span class="code-line">    <span class="ss">brd: </span><span class="no">ExtrasDeCont</span><span class="o">::</span><span class="no">Rules</span><span class="o">::</span><span class="no">Brd</span><span class="p">,</span></span><span class="code-line">    <span class="ss">ing: </span><span class="no">ExtrasDeCont</span><span class="o">::</span><span class="no">Rules</span><span class="o">::</span><span class="no">Ing</span><span class="p">,</span></span><span class="code-line">    <span class="ss">revolut: </span><span class="no">ExtrasDeCont</span><span class="o">::</span><span class="no">Rules</span><span class="o">::</span><span class="no">Revolut</span><span class="p">,</span></span><span class="code-line">    <span class="ss">unicredit: </span><span class="no">ExtrasDeCont</span><span class="o">::</span><span class="no">Rules</span><span class="o">::</span><span class="no">UniCredit</span></span><span class="code-line">  <span class="p">}.</span><span class="nf">freeze</span></span><span class="code-line"></span><span class="code-line">  <span class="k">class</span> <span class="o">&lt;&lt;</span> <span class="nb">self</span></span><span class="code-line">    <span class="c1"># Parses a PDF bank statement and returns structured transactions.</span></span><span class="code-line">    <span class="c1">#</span></span><span class="code-line">    <span class="c1"># @param file [String, Pathname, IO] path to the PDF file or an IO-like object</span></span><span class="code-line">    <span class="c1"># @param bank [Symbol] the bank identifier (:unicredit, :revolut, etc.)</span></span><span class="code-line">    <span class="c1"># @return [Array&lt;ExtrasDeCont::Transaction&gt;]</span></span><span class="code-line">    <span class="c1"># @raise [ArgumentError] if the bank is not supported</span></span><span class="code-line">    <span class="k">def</span> <span class="nf">parse</span><span class="p">(</span><span class="n">file</span><span class="p">,</span> <span class="n">bank</span><span class="p">:)</span></span><span class="code-line">      <span class="n">rule_class</span> <span class="o">=</span> <span class="no">BANK_RULES</span><span class="p">[</span><span class="n">bank</span><span class="p">]</span></span><span class="code-line">      <span class="k">raise</span> <span class="no">ArgumentError</span><span class="p">,</span> <span class="s2">"Unsupported bank: </span><span class="si">#{</span><span class="n">bank</span><span class="si">}</span><span class="s2">. Supported banks: </span><span class="si">#{</span><span class="no">BANK_RULES</span><span class="p">.</span><span class="nf">keys</span><span class="p">.</span><span class="nf">join</span><span class="p">(</span><span class="s2">", "</span><span class="p">)</span><span class="si">}</span><span class="s2">"</span> <span class="k">unless</span> <span class="n">rule_class</span></span><span class="code-line"></span><span class="code-line">      <span class="nb">p</span> <span class="o">=</span> <span class="no">ExtrasDeCont</span><span class="o">::</span><span class="no">Parser</span><span class="p">.</span><span class="nf">new</span><span class="p">(</span><span class="n">file</span><span class="p">)</span></span><span class="code-line">      <span class="nb">p</span><span class="p">.</span><span class="nf">parse_with</span><span class="p">(</span><span class="n">rule_class</span><span class="p">.</span><span class="nf">new</span><span class="p">)</span></span><span class="code-line">    <span class="k">end</span></span><span class="code-line">  <span class="k">end</span></span><span class="code-line"><span class="k">end</span></span><span class="code-line"></span><span class="code-line"><span class="n">loader</span><span class="p">.</span><span class="nf">eager_load</span></span></code></pre></div></div>

<p>Note that I added this inflection in order to keep <code class="language-plaintext highlighter-rouge">unicredit.rb</code> refer to <code class="language-plaintext highlighter-rouge">UniCredit</code>.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line"><span class="n">loader</span><span class="p">.</span><span class="nf">inflector</span><span class="p">.</span><span class="nf">inflect</span><span class="p">(</span></span><span class="code-line">  <span class="s2">"unicredit"</span> <span class="o">=&gt;</span> <span class="s2">"UniCredit"</span></span><span class="code-line"><span class="p">)</span></span></code></pre></div></div>

<p>Additionally, the file structure of the gem looks like this:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="code-line">.</span><span class="code-line">├── AGENTS.md</span><span class="code-line">├── bin</span><span class="code-line">│   └── example.rb</span><span class="code-line">├── changelog.md</span><span class="code-line">├── diagram.md</span><span class="code-line">├── entities.json</span><span class="code-line">├── extras_de_cont.gemspec</span><span class="code-line">├── Gemfile</span><span class="code-line">├── Gemfile.lock</span><span class="code-line">├── lib</span><span class="code-line">│   ├── extras_de_cont</span><span class="code-line">│   │   ├── parser.rb</span><span class="code-line">│   │   ├── rules</span><span class="code-line">│   │   │   ├── base.rb</span><span class="code-line">│   │   │   ├── brd.rb</span><span class="code-line">│   │   │   ├── ing.rb</span><span class="code-line">│   │   │   ├── revolut.rb</span><span class="code-line">│   │   │   └── unicredit.rb</span><span class="code-line">│   │   └── transaction.rb</span><span class="code-line">│   └── extras_de_cont.rb</span><span class="code-line">├── LICENSE</span><span class="code-line">├── mempalace.yaml</span><span class="code-line">├── opencode.json</span><span class="code-line">├── pkg</span><span class="code-line">│   ├── extras_de_cont-1.0.2.gem</span><span class="code-line">│   ├── extras_de_cont-1.1.0.gem</span><span class="code-line">│   ├── extras_de_cont-1.2.0.gem</span><span class="code-line">│   ├── extras_de_cont-1.3.0.gem</span><span class="code-line">│   └── extras_de_cont-1.4.0.gem</span><span class="code-line">├── Rakefile</span><span class="code-line">├── README.md</span><span class="code-line">├── sig</span><span class="code-line">│   └── extras_de_cont</span><span class="code-line">│       ├── extras_de_cont.rbs</span><span class="code-line">│       ├── parser.rbs</span><span class="code-line">│       ├── rules</span><span class="code-line">│       │   ├── base.rbs</span><span class="code-line">│       │   └── brd.rbs</span><span class="code-line">│       └── transaction.rbs</span><span class="code-line">└── test</span><span class="code-line">    └── extras_de_cont</span><span class="code-line">        └── rules</span><span class="code-line">            ├── brd_rule_test.rb</span><span class="code-line">            ├── ing_rule_test.rb</span><span class="code-line">            ├── revolut_rule_test.rb</span><span class="code-line">            └── unicredit_rule_test.rb</span><span class="code-line"></span><span class="code-line">12 directories, 35 files</span></code></pre></div></div>

<h1 id="conclusion">Conclusion</h1>

<p>Zeitwerk is a nice ruby gem that removes the need of requiring files manually. If you browse some Ruby code and all
the <code class="language-plaintext highlighter-rouge">require_relative</code> are missing then the projects probably uses Zeitwerk.</p>

<p>In order for Zeitwerk to work you will need to have a certain directory structure, but Zeitwerk is highly customizable.</p>

<p>Thanks for reading!</p>]]></content><author><name>Denis</name></author><category term="Programming" /><category term="Ruby" /><category term="ruby" /><category term="programming" /><summary type="html"><![CDATA[Introduction Hello everyone! As I was playing around with the Ruby programming language when building a Rails application I came across Zeitwerk, a library that loads all your ruby files automatically and I wanted to write about it. The main idea behind the library is that your projects needs to follow a certain file structure and then the lib will load all the ruby files, eliminating the necessity to write require_relative 'x'. This is nice because it keeps the code structured in an opinionated way and saves some keystrokes from writing import files. It did confuse me at first when I browsed the source code of Gitlab and I didn’t see any imports, and that is because they use Rails and Zeitwerk. Usage To use the library your project needs to follow the following folder structure: lib/my_gem.rb -&gt; MyGemlib/my_gem/foo.rb -&gt; MyGem::Foolib/my_gem/bar_baz.rb -&gt; MyGem::BarBazlib/my_gem/woo/zoo.rb -&gt; MyGem::Woo::Zoo You can also fine tune it by collapsing directories, ignoring directories or adding inflections. (eg: unicredit.rb to UniCredit, without inflections it would be lowercase C) Once you have that structure, you can install it by typing bundle add zeitwerk and then all you need to do is write some boilerplate code to set it up. Application If you’re writing an application then you can call the library in your main file, specifying which directories Zeitwerk should load. require "zeitwerk"# Note: there is no require_relative "huffman" because Zeitwerk loaded it automatically.def main huffman = Huffman.new("huffman.md") content = huffman.encode print content.leftendif __FILE__ == $0 # Only three lines of code needed loader = Zeitwerk::Loader.new loader.push_dir(File.expand_path("./lib")) loader.setup mainend The structure for this application project looks like this: ├── Gemfile├── Gemfile.lock├── huffman.md├── lib│   ├── huffman│   │   └── base_exception.rb│   ├── huffman.rb│   └── tree│   ├── base_node.rb│   ├── internal_node.rb│   └── leaf_node.rb├── main.rb # The main file, entrypoint├── Rakefile.rb└── test └── huffman_test.rb That is basically it. Gem (Library) When writing a library gem, you can use Zeitwerk::Loader.for_gem. In my ExtrasDeCont gem I have the following entrypoint: # frozen_string_literal: truerequire 'zeitwerk'loader = Zeitwerk::Loader.for_gemloader.inflector.inflect( "unicredit" =&gt; "UniCredit")loader.setup# The ExtrasDeCont module contains utilities for parsing bank statements.module ExtrasDeCont # Map of supported banks (symbol → rule class) BANK_RULES = { brd: ExtrasDeCont::Rules::Brd, ing: ExtrasDeCont::Rules::Ing, revolut: ExtrasDeCont::Rules::Revolut, unicredit: ExtrasDeCont::Rules::UniCredit }.freeze class &lt;&lt; self # Parses a PDF bank statement and returns structured transactions. # # @param file [String, Pathname, IO] path to the PDF file or an IO-like object # @param bank [Symbol] the bank identifier (:unicredit, :revolut, etc.) # @return [Array&lt;ExtrasDeCont::Transaction&gt;] # @raise [ArgumentError] if the bank is not supported def parse(file, bank:) rule_class = BANK_RULES[bank] raise ArgumentError, "Unsupported bank: #{bank}. Supported banks: #{BANK_RULES.keys.join(", ")}" unless rule_class p = ExtrasDeCont::Parser.new(file) p.parse_with(rule_class.new) end endendloader.eager_load Note that I added this inflection in order to keep unicredit.rb refer to UniCredit. loader.inflector.inflect( "unicredit" =&gt; "UniCredit") Additionally, the file structure of the gem looks like this: .├── AGENTS.md├── bin│   └── example.rb├── changelog.md├── diagram.md├── entities.json├── extras_de_cont.gemspec├── Gemfile├── Gemfile.lock├── lib│   ├── extras_de_cont│   │   ├── parser.rb│   │   ├── rules│   │   │   ├── base.rb│   │   │   ├── brd.rb│   │   │   ├── ing.rb│   │   │   ├── revolut.rb│   │   │   └── unicredit.rb│   │   └── transaction.rb│   └── extras_de_cont.rb├── LICENSE├── mempalace.yaml├── opencode.json├── pkg│   ├── extras_de_cont-1.0.2.gem│   ├── extras_de_cont-1.1.0.gem│   ├── extras_de_cont-1.2.0.gem│   ├── extras_de_cont-1.3.0.gem│   └── extras_de_cont-1.4.0.gem├── Rakefile├── README.md├── sig│   └── extras_de_cont│   ├── extras_de_cont.rbs│   ├── parser.rbs│   ├── rules│   │   ├── base.rbs│   │   └── brd.rbs│   └── transaction.rbs└── test └── extras_de_cont └── rules ├── brd_rule_test.rb ├── ing_rule_test.rb ├── revolut_rule_test.rb └── unicredit_rule_test.rb12 directories, 35 files Conclusion Zeitwerk is a nice ruby gem that removes the need of requiring files manually. If you browse some Ruby code and all the require_relative are missing then the projects probably uses Zeitwerk. In order for Zeitwerk to work you will need to have a certain directory structure, but Zeitwerk is highly customizable. Thanks for reading!]]></summary></entry></feed>